Releases: unslothai/unsloth
Release list
Large Performance Gains + Fixes

This is a large performance and reliability + bug fix release for Unsloth
Highlights
- 1.2-1.7x faster diffusion. AMD 20% perf boost vs ROCM via Vulkan
- 2x faster updating, remove SAC + AV false positives for Windows
- Blender MCP, detect Hermes, AMD gibberish fixed (reported to AMD)
- Over 250+ bug fixes, 60% smaller binaries and performance improvements
- Strix iGPU BIOS popup - 3x faster inference if more VRAM for iGPU
- Updated PyTorch to 2.11 from 2.10 - 2.14 will be soon. MLX improvements
- Default to gpt-6-astra for Codex logins and improve OpenAI API processing
- MLX fixed when self healing / updating, causing slowdowns for inf + training
- Fix AppImage being very laggy. Fixed RAG upload issues stuck at 28% and API issues
- New Docker image published at https://hub.docker.com/r/unsloth/unsloth for Studio and notebooks
Performance Boosts
- Diffusion is 1.2x to 1.7x faster for INT8 / FP8 pathways - all models accelerated.
- 23% faster prompt processing and 8% faster generation on Strix Halo.
- Gated-delta models now train up to 25% faster on Apple Silicon.
- Quantized MLX KV caches use up to 74% less prompt memory than before.
AMD + Windows
- Strix Halo and Strix Point now default to Vulkan for faster inference.
- AMD iGPUs without ROCm now use Vulkan instead of CPU on Linux.
- Windows llama.cpp binaries are now signed to reduce Smart App Control blocks.
- Windows now clearly explains when code integrity blocks model loading.
- Reinstalling Unsloth on Windows keeps your supported PyTorch version.
MLX + Apple Silicon
- Fresh Mac installs keep MLX training and exports working.
- Fine-tune with DoRA and more DPO loss types on Apple Silicon.
- Batched MLX generation now streams and samples each chat independently.
- More multimodal models can be fine-tuned using text-only datasets.
Studio + API
- RAG and document uploads are faster, show clearer progress and no longer appear stuck.
- Studio menus, Find and Settings now open more smoothly.
- GPT-6 Astra is available for Codex logins with Low through Max reasoning controls.
- Improved OpenAI-compatible API streaming, audio input and model loading.
- AppImage builds are more reliable with a pinned release toolchain.
Installs + Docker
- PyTorch 2.11 is now the default across supported installers.
- New NVIDIA Docker images for training and Studio, from Turing to Blackwell.
- Native AMD64 and ARM64 images are available from Docker Hub.
- The Unsloth Python package is now >60% smaller.
Docker: https://hub.docker.com/r/unsloth/unsloth
Download Unsloth Desktop
Unsloth Desktop is free and open source. Download it for:
- Windows
- macOS
- Linux
What's Changed
- Publish only the wheel to PyPI, not the sdist by @danielhanchen in #10202
- Bump install.sh / install.ps1 pin to unsloth>=2026.9.2 by @danielhanchen in #10203
- Add DeepSeek Harness to unsloth start by @NilayYadav in #10097
- Studio: stop generating when the client goes away by @NilayYadav in #10096
- Studio: keep what you typed with an image when a chat is shortened by @NilayYadav in #10165
- Order the Ollama stop-token scan instead of leaving it to a set by @vineethsaivs in #10101
- Studio: replay a web_search result the way the client sent it by @Lyxot in #10131
- Studio: say when a chat is too long instead of showing a raw error by @NilayYadav in #10090
- Restore the comment tails the trim cut off by @danielhanchen in #10205
- Studio: accept subtitle, caption and the rest of the common attachment formats by @shimmyshimmer in #9738
- Studio: count only this adapter's engines in the Windows AMD GPU utilization by @LeoBorcherding in #9317
- Fix diffusion offload host RAM retention by @wasimysaid in #10184
- Let audio models load into CPU RAM instead of the GPU by @shimmyshimmer in #10054
- Stop the zoo digest pin living in two places by @danielhanchen in #10206
- Format test_video_backend.py the way the pinned ruff wants by @danielhanchen in #10235
- Security audit: re-approve the four torch findings that 2.14.0 opened by @danielhanchen in #10233
- unsloth_cli tests: stop the mklink kwargs assertion breaking on an unrelated keyword by @danielhanchen in #10231
- Pin the multi-turn determinism probe to a backend that can be deterministic by @danielhanchen in #10234
- CI: stop grep -c || echo 0 producing a two-line count by @danielhanchen in #10232
- Security audit: re-approve the huggingface-hub backoff loop for 1.30.0 by @danielhanchen in #10244
- Stop the stall-window comparison being decided by one noisy sample by @danielhanchen in #10246
- Studio: report a cut off /v1/responses turn as incomplete by @NilayYadav in #10225
- Studio: keep a still-advancing llama.cpp prefill from timing out by @oobabooga in #10172
- Studio: bring the Llasa top_p default inside the range the API accepts by @danielhanchen in #9194
- CLI: pass --hf-token to the export checkpoint load by @NilayYadav in #10218
- Pin AppImage plugin to a versioned release by @wasimysaid in #10201
- Studio: thread hf_token through load_and_format_dataset by @KrishPatel1905 in #8924
- Studio: stop the update banners floating off the corner by @oobabooga in #10229
- fix(studio): stop handing a wildcard bind's public IP to LAN peers by @amanyagami in #9912
- Studio: report free memory on Mac as what is actually free by @NilayYadav in #10224
- Studio: match the update banner tests on classes, not on file substrings by @danielhanchen in #10267
- Studio: size a Deep Research run to the model it actually runs on by @NilayYadav in #10220
- Studio: fall back when a page declares a charset we do not know by @NilayYadav in #10221
- Studio: pin which rejection site the confirm-stream tests assert by @danielhanchen in #10284
- Studio: turn the generation prompt off on the final answer continuation by @NilayYadav in #10219
- Studio: let the API load settings panel forget an entry by @NilayYadav in #10160
- Windows torch release preservation and a torch 2.11 default across installers by @danielhanchen in #7256
- Add cu128/cu126/cu130 torch 2.11.0 extras (torch2110) with xformers 0.0.35 by @danielhanchen in #6955
- Studio: assert the write ordering, not what the write resolves to by @danielhanchen in #10289
- Kaggle: fix the nightly, which has never once got as far as Kaggle by @danielhanchen in #10270
- Keep probing for a usable nvidia-smi before falling back to ROCm on Windows by @danielhanchen in #4958
- Trim comments in studio/frontend chat, model picker and media features by @danielhanchen in #10114
- Add a dispatch-only Docker Hub credential probe by @danielhanchen in #10291
- Fix Studio find-in-page correctness and typing by @wasimysaid in #10209
- Studio: stop exports timing out while they are still working by @NilayYadav in #10258
- Stop unsloth chat from reloading a model the server already has by @NilayYadav in #10257
- Studio: stop hiding every model pulled with ollama pull by @NilayYadav in #10222
- Anchor studio source slices on declarations, not on comment text by @danielhanchen in #10297
- Studio: fix Restore settings breaking preset saving by @NilayYadav in #10256
- Lazy-load Studio entry surfaces by @wasimysaid in #10236
- Restore persisted Studio resource monitor by @wasimysaid in #10237
- fix(frontend): render data-URI images in chat markdown by @CelesteHeartsong in #10269
- Fix Hub GGUF fit estimates for companion files by @Imagineer99 in #10249
- Pin the auth mount gate to its behaviour, not one spelling of the guard by @danielhanchen in #10307
- Trim comments in tests, scripts, CI helpers and unsloth_cli by @danielhanchen in https://github...
Contributors


Assets 8
Large Perf Improvements + Fixes
This is a large performance and reliability + bug fix release for Unsloth
Highlights
- AMD uses Vulkan by default - 20% perf boost for prefill, decoding vs ROCM
- Windows llama-server.exe is now signed, reducing false positives for SAC
- AMD gibberish issues in Strix, iGPUs fixed in (upstream - reported to AMD)
- Over 200+ bug fixes, 50% smaller binaries and performance improvements
- Updated PyTorch to 2.11 from 2.10 - 2.14 will be soon. MLX improvements
- Default to gpt-6-astra for Codex logins and improve OpenAI API processing
- MLX fixed when self healing / updating, causing slowdowns for inf + training
- Fix AppImage being very laggy. Fixed RAG upload issues stuck at 28% and API issues
- New Docker image published at https://hub.docker.com/r/unsloth/unsloth for Studio and notebooks
AMD + Windows
- Strix Halo and Strix Point now default to Vulkan for faster inference.
- Up to 23% faster prompt processing and 8% faster generation on Strix Halo.
- AMD iGPUs without ROCm now use Vulkan instead of CPU on Linux.
- Windows llama.cpp binaries are now signed to reduce Smart App Control blocks.
- Windows now clearly explains when code integrity blocks model loading.
- Reinstalling Unsloth on Windows keeps your supported PyTorch version.
MLX + Apple Silicon
- Gated-delta models now train up to 25% faster on Apple Silicon.
- Quantized MLX KV caches use up to 74% less prompt memory than before.
- Fresh Mac installs keep MLX training and exports working.
- Fine-tune with DoRA and more DPO loss types on Apple Silicon.
- Batched MLX generation now streams and samples each chat independently.
- More multimodal models can be fine-tuned using text-only datasets.
Studio + API
- RAG and document uploads are faster, show clearer progress and no longer appear stuck.
- Studio menus, Find and Settings now open more smoothly.
- GPT-6 Astra is available for Codex logins with Low through Max reasoning controls.
- Improved OpenAI-compatible API streaming, audio input and model loading.
- AppImage builds are more reliable with a pinned release toolchain.
Installs + Docker
- PyTorch 2.11 is now the default across supported installers.
- New NVIDIA Docker images for training and Studio, from Turing to Blackwell.
- Native AMD64 and ARM64 images are available from Docker Hub.
- The Unsloth Python package is now 44% smaller.
Docker: https://hub.docker.com/r/unsloth/unsloth
Download Unsloth Desktop
Unsloth Desktop is free and open source. Download it for:
- Windows
- macOS
- Linux
What's Changed
- Publish only the wheel to PyPI, not the sdist by @danielhanchen in #10202
- Bump install.sh / install.ps1 pin to unsloth>=2026.9.2 by @danielhanchen in #10203
- Add DeepSeek Harness to unsloth start by @NilayYadav in #10097
- Studio: stop generating when the client goes away by @NilayYadav in #10096
- Studio: keep what you typed with an image when a chat is shortened by @NilayYadav in #10165
- Order the Ollama stop-token scan instead of leaving it to a set by @vineethsaivs in #10101
- Studio: replay a web_search result the way the client sent it by @Lyxot in #10131
- Studio: say when a chat is too long instead of showing a raw error by @NilayYadav in #10090
- Restore the comment tails the trim cut off by @danielhanchen in #10205
- Studio: accept subtitle, caption and the rest of the common attachment formats by @shimmyshimmer in #9738
- Studio: count only this adapter's engines in the Windows AMD GPU utilization by @LeoBorcherding in #9317
- Fix diffusion offload host RAM retention by @wasimysaid in #10184
- Let audio models load into CPU RAM instead of the GPU by @shimmyshimmer in #10054
- Stop the zoo digest pin living in two places by @danielhanchen in #10206
- Format test_video_backend.py the way the pinned ruff wants by @danielhanchen in #10235
- Security audit: re-approve the four torch findings that 2.14.0 opened by @danielhanchen in #10233
- unsloth_cli tests: stop the mklink kwargs assertion breaking on an unrelated keyword by @danielhanchen in #10231
- Pin the multi-turn determinism probe to a backend that can be deterministic by @danielhanchen in #10234
- CI: stop grep -c || echo 0 producing a two-line count by @danielhanchen in #10232
- Security audit: re-approve the huggingface-hub backoff loop for 1.30.0 by @danielhanchen in #10244
- Stop the stall-window comparison being decided by one noisy sample by @danielhanchen in #10246
- Studio: report a cut off /v1/responses turn as incomplete by @NilayYadav in #10225
- Studio: keep a still-advancing llama.cpp prefill from timing out by @oobabooga in #10172
- Studio: bring the Llasa top_p default inside the range the API accepts by @danielhanchen in #9194
- CLI: pass --hf-token to the export checkpoint load by @NilayYadav in #10218
- Pin AppImage plugin to a versioned release by @wasimysaid in #10201
- Studio: thread hf_token through load_and_format_dataset by @KrishPatel1905 in #8924
- Studio: stop the update banners floating off the corner by @oobabooga in #10229
- fix(studio): stop handing a wildcard bind's public IP to LAN peers by @amanyagami in #9912
- Studio: report free memory on Mac as what is actually free by @NilayYadav in #10224
- Studio: match the update banner tests on classes, not on file substrings by @danielhanchen in #10267
- Studio: size a Deep Research run to the model it actually runs on by @NilayYadav in #10220
- Studio: fall back when a page declares a charset we do not know by @NilayYadav in #10221
- Studio: pin which rejection site the confirm-stream tests assert by @danielhanchen in #10284
- Studio: turn the generation prompt off on the final answer continuation by @NilayYadav in #10219
- Studio: let the API load settings panel forget an entry by @NilayYadav in #10160
- Windows torch release preservation and a torch 2.11 default across installers by @danielhanchen in #7256
- Add cu128/cu126/cu130 torch 2.11.0 extras (torch2110) with xformers 0.0.35 by @danielhanchen in #6955
- Studio: assert the write ordering, not what the write resolves to by @danielhanchen in #10289
- Kaggle: fix the nightly, which has never once got as far as Kaggle by @danielhanchen in #10270
- Keep probing for a usable nvidia-smi before falling back to ROCm on Windows by @danielhanchen in #4958
- Trim comments in studio/frontend chat, model picker and media features by @danielhanchen in #10114
- Add a dispatch-only Docker Hub credential probe by @danielhanchen in #10291
- Fix Studio find-in-page correctness and typing by @wasimysaid in #10209
- Studio: stop exports timing out while they are still working by @NilayYadav in #10258
- Stop unsloth chat from reloading a model the server already has by @NilayYadav in #10257
- Studio: stop hiding every model pulled with ollama pull by @NilayYadav in #10222
- Anchor studio source slices on declarations, not on comment text by @danielhanchen in #10297
- Studio: fix Restore settings breaking preset saving by @NilayYadav in #10256
- Lazy-load Studio entry surfaces by @wasimysaid in #10236
- Restore persisted Studio resource monitor by @wasimysaid in #10237
- fix(frontend): render data-URI images in chat markdown by @CelesteHeartsong in #10269
- Fix Hub GGUF fit estimates for companion files by @Imagineer99 in #10249
- Pin the auth mount gate to its behaviour, not one spelling of the guard by @danielhanchen in #10307
- Trim comments in tests, scripts, CI helpers and unsloth_cli by @danielhanchen in #10113
- Add Unsloth Docker images (base + Studio) for any NVIDIA GPU host, Ampere through Blackwell by @danielhanchen i...
Contributors
Assets 8
2x Faster Qwen3.8-Flash + GLM-5.3-Flash MTP
Run Qwen3.8-Flash-Next and GLM-5.3-Flash up to 2x faster with MTP. MTP is enabled by default, you can still disable it.
Also our new release includes 170+ training, chat, hardware, and performance improvements.
Highlights
- Smoother model loading (less errors) across local servers and connected providers.
- Faster and less laggy UI with follow-up turns much faster for all chats.
- Safer chat edits that preserve tool cards, reply details, and conversation branches.
- New local media APIs for video, audio, and MLX-served models.
- New audio support with new models, progress tracking including: MiniMax-Music3, Higgs, MOSS and more!
- Improved multi-GPU planning, memory fitting, and split-model training.
- Strengthened AMD/ROCm detection, installation, and GPU compatibility.
- Upgraded MCP, Deep Research, OAuth, and agent tool reliability.
Qwen3.8-Flash + GLM-5.3-Flash
- Qwen and GLM now generate faster with MTP enabled by default.
- Use GLM tools across longer, multi-turn chats.
- Qwen automatically applies the recommended settings for thinking and non-thinking modes.
Download Qwen3.8-Flash-Next and GLM-5.3-Flash. See the Qwen guide and GLM guide for recommended settings and available GGUFs.
Faster MLX inference
- Fine-tune both large MoE models with text or images on Apple Silicon using MLX.
- Long Qwen chats now run much faster on Mac, with follow-up turns up to 30x faster.
- MLX models now use their full context size and support much longer batched generation.
- MLX releases GPU memory more cleanly between generation bursts and model switches.
- Serve MLX models through Unsloth's OpenAI-compatible API.
Audio
- Added support for MiniMax-Music3, Higgs, MOSS audio models.
- Added live progress updates while audio is being generated.
- Audio clips can now be archived and managed.
- Improved reliability with custom TTS playback fixes, Whisper pairing checks, and stronger audio testing.
Chat + tools
- Run several tool calls at once without mixing up their arguments.
- Keep tools available when chatting with images.
- Each chat keeps its MCP connection for faster tool calls.
- Local models can edit code using Codex’s apply_patch tool.
- Continue long chats with images and other media using Auto Compaction.
- Review and approve Deep Research plans before research starts.
Training + hardware
- Train larger models across multiple GPUs with automatic placement.
- AMD installs choose the best build across Windows and Linux, with BF16 on more GPUs.
- Export GLM-5.3 MLX fine-tunes to GGUF.
- Choose custom GGUF shard sizes and save locations.
API + Desktop
- Generate videos through the new OpenAI-compatible Videos API.
- Updates download in the background and install when you restart.
- Choose a custom port for LAN access.
- Generate audio with Higgs, MOSS and MiniMax models.
- Track audio generation progress and archive finished clips.
- Model downloads show clearer progress and can switch from Xet to HTTP automatically.
Download Unsloth Desktop
Unsloth Desktop is free and open source. Download it for:
- Windows
- macOS
- Linux
What's Changed
- Put the smart offload planner back behind its flag by @danielhanchen in #9862
- Studio: stop the per-chunk autosave writing back messages the server owns by @danielhanchen in #9865
- Bump install.sh / install.ps1 pins to unsloth>=2026.8.22 by @danielhanchen in #9868
- Fix Studio hydrating synced GGUF files before selection by @milewski in #9539
- Fix datasets PyArrow registration after failed warm import by @Imagineer99 in #9626
- fix(studio): stop offering a transformers upgrade where it cannot load anything by @Lyxot in #9878
- Fix Studio CPT overwriting LFM2 all-linear LoRA targets by @Souravrajvi0 in #9870
- fix(studio): accept trailing slash for model discovery by @Imagineer99 in #9876
- studio: accept shared youtube clipboard links by @mahiatlinux in #9903
- studio: tell users when a canvas is blocked by the network access setting by @NilayYadav in #9894
- studio: fix streamed tool calls in studio api monitor by @Etherll in #9896
- studio: serve installed mlx models through the openai-compatible api by @mahiatlinux in #8768
- Fix sidebar footer width and context menu radius by @shimmyshimmer in #9918
- strip inherited claude provider routing from local agent launches by @Souravrajvi0 in #9871
- studio: honor a cancelled load inside the llama-server health wait by @NilayYadav in #9893
- fix model hub recent sorting for on-device models by @Imagineer99 in #9642
- add a setting that tells the model the current date by @mahiatlinux in #8879
- studio: fix lan address actions and launch bind reporting by @Lyxot in #9170
- rag: avoid re-hashing linked-folder snapshots in start_ingestion by @DhruvaMyakeri in #9913
- fix(studio): coalesce concurrent keyless-settings reads to stop SQLite thundering herd by @Greninja44 in #9911
- Studio: add the OpenAI videos API on /v1/videos by @NilayYadav in #9891
- Clarify tool approval copy by @Imagineer99 in #8738
- Pin Claude Code to the loaded model's real context window by @NilayYadav in #9940
- studio: drop the schema bounds llama.cpp's grammar engine cannot compile by @Lyxot in #9923
- Fix shell selection for remote Agents commands by @Imagineer99 in #8844
- Studio: accept the loadConfig keys a saved system-prompt preset already sends by @indrajeetapache in #9881
- Studio: compact long chats with media attachments by @Imagineer99 in #9476
- Studio: add Higgs, MOSS, and MiniMax audio models by @Etherll in #8794
- studio: add ordered arguments to mcp server settings by @Etherll in #9943
- studio: list route-aware models through the openai api by @NilayYadav in #9892
- fix(studio): repair custom TTS endpoint test and playback by @Souravrajvi0 in #9905
- Studio: render escaped inline math in lists by @Imagineer99 in #9796
- deprecate unsupported custom prompt templates by @vineethsaivs in #8938
- Restore UNSLOTH_RETURN_LOGITS after prediction_step instead of forcing it to 0 by @danielhanchen in #6239
- Studio: update in the background and restart when ready by @NilayYadav in #9890
- Serve every MiniMax H3 asset from unsloth rather than a community repack by @danielhanchen in #8832
- fix(studio): gate external tool nudges and preserve retry context by @Biotrioo in #9125
- Chat: let the LoRA compare rehydrate a pair the generalized compare saved by @lonexreb in #9908
- fix: expose codex apply_patch for local models (#9114) by @Biotrioo in #9121
- Fix duplicate GGUF rows in custom model folders by @Imagineer99 in #9975
- Revert "fix(studio): gate external tool nudges and preserve retry context" by @danielhanchen in #9990
- studio: isolate mcp browser test state by @mahiatlinux in #9951
- Fix three CI regressions: code-span anchor, load-dispatch anchor, recordless pip install by @danielhanchen in #9959
- studio: fix audio ci tests by @mahiatlinux in #9953
- studio: fix openai route ci tests by @mahiatlinux in #9952
- Skip the inline-code mask when every backtick is inside a fence by @danielhanchen in #9991
- stop the planner withholding a split reserve from one card, and price physical cores by @danielhanchen in #9863
- Parse the downloaded model mapper instead of exec'ing it by @danielhanchen in #9777
- Recapture the control leg reference against the fixed loss normalisation by @danielhanchen in #9569
- Stop os.dup2 alone being a reverse shell, and allowlist the zoo URL guard by @danielhanchen in #9994
- Give the in-venv CLI tests a writable STUDIO_HOME by @danielhanch...
Contributors


Assets 8
2x Faster Qwen3.8-Flash + GLM-5.3-Flash MTP
Run Qwen3.8-Flash-Next and GLM-5.3-Flash up to 2x faster with MTP. MTP is enabled by default, you can still disable it.
Also our new release includes 170+ training, chat, hardware, and performance improvements.
Highlights
- Smoother model loading (less errors) across local servers and connected providers.
- Safer chat edits that preserve tool cards, reply details, and conversation branches.
- New local media APIs for video, audio, and MLX-served models.
- New audio support with new models, progress tracking including: MiniMax-Music3, Higgs, MOSS and more!
- Improved multi-GPU planning, memory fitting, and split-model training.
- Ctrl+F Search now works.
- Strengthened AMD/ROCm detection, installation, and GPU compatibility.
- Upgraded MCP, Deep Research, OAuth, and agent tool reliability.
Qwen3.8-Flash + GLM-5.3-Flash
- Qwen and GLM now generate faster with MTP enabled by default.
- Use GLM tools across longer, multi-turn chats.
- Qwen automatically applies the recommended settings for thinking and non-thinking modes.
Download Qwen3.8-Flash-Next and GLM-5.3-Flash. See the Qwen guide and GLM guide for recommended settings and available GGUFs.
Faster MLX inference
- Fine-tune both large MoE models with text or images on Apple Silicon using MLX.
- Long Qwen chats now run much faster on Mac, with follow-up turns up to 30x faster.
- MLX models now use their full context size and support much longer batched generation.
- MLX releases GPU memory more cleanly between generation bursts and model switches.
- Serve MLX models through Unsloth's OpenAI-compatible API.
Audio
- Added support for MiniMax-Music3, Higgs, MOSS audio models.
- Added live progress updates while audio is being generated.
- Audio clips can now be archived and managed.
- Improved reliability with custom TTS playback fixes, Whisper pairing checks, and stronger audio testing.
Chat + tools
- Run several tool calls at once without mixing up their arguments.
- Keep tools available when chatting with images.
- Each chat keeps its MCP connection for faster tool calls.
- Local models can edit code using Codex’s apply_patch tool.
- Continue long chats with images and other media using Auto Compaction.
- Review and approve Deep Research plans before research starts.
Training + hardware
- Train larger models across multiple GPUs with automatic placement.
- AMD installs choose the best build across Windows and Linux, with BF16 on more GPUs.
- Export GLM-5.3 MLX fine-tunes to GGUF.
- Choose custom GGUF shard sizes and save locations.
API + Desktop
- Generate videos through the new OpenAI-compatible Videos API.
- Updates download in the background and install when you restart.
- Choose a custom port for LAN access.
- Generate audio with Higgs, MOSS and MiniMax models.
- Track audio generation progress and archive finished clips.
- Model downloads show clearer progress and can switch from Xet to HTTP automatically.
Download Unsloth Desktop
Unsloth Desktop is free and open source. Download it for:
- Windows
- macOS
- Linux
What's Changed
- Put the smart offload planner back behind its flag by @danielhanchen in #9862
- Studio: stop the per-chunk autosave writing back messages the server owns by @danielhanchen in #9865
- Bump install.sh / install.ps1 pins to unsloth>=2026.8.22 by @danielhanchen in #9868
- Fix Studio hydrating synced GGUF files before selection by @milewski in #9539
- Fix datasets PyArrow registration after failed warm import by @Imagineer99 in #9626
- fix(studio): stop offering a transformers upgrade where it cannot load anything by @Lyxot in #9878
- Fix Studio CPT overwriting LFM2 all-linear LoRA targets by @Souravrajvi0 in #9870
- fix(studio): accept trailing slash for model discovery by @Imagineer99 in #9876
- studio: accept shared youtube clipboard links by @mahiatlinux in #9903
- studio: tell users when a canvas is blocked by the network access setting by @NilayYadav in #9894
- studio: fix streamed tool calls in studio api monitor by @Etherll in #9896
- studio: serve installed mlx models through the openai-compatible api by @mahiatlinux in #8768
- Fix sidebar footer width and context menu radius by @shimmyshimmer in #9918
- strip inherited claude provider routing from local agent launches by @Souravrajvi0 in #9871
- studio: honor a cancelled load inside the llama-server health wait by @NilayYadav in #9893
- fix model hub recent sorting for on-device models by @Imagineer99 in #9642
- add a setting that tells the model the current date by @mahiatlinux in #8879
- studio: fix lan address actions and launch bind reporting by @Lyxot in #9170
- rag: avoid re-hashing linked-folder snapshots in start_ingestion by @DhruvaMyakeri in #9913
- fix(studio): coalesce concurrent keyless-settings reads to stop SQLite thundering herd by @Greninja44 in #9911
- Studio: add the OpenAI videos API on /v1/videos by @NilayYadav in #9891
- Clarify tool approval copy by @Imagineer99 in #8738
- Pin Claude Code to the loaded model's real context window by @NilayYadav in #9940
- studio: drop the schema bounds llama.cpp's grammar engine cannot compile by @Lyxot in #9923
- Fix shell selection for remote Agents commands by @Imagineer99 in #8844
- Studio: accept the loadConfig keys a saved system-prompt preset already sends by @indrajeetapache in #9881
- Studio: compact long chats with media attachments by @Imagineer99 in #9476
- Studio: add Higgs, MOSS, and MiniMax audio models by @Etherll in #8794
- studio: add ordered arguments to mcp server settings by @Etherll in #9943
- studio: list route-aware models through the openai api by @NilayYadav in #9892
- fix(studio): repair custom TTS endpoint test and playback by @Souravrajvi0 in #9905
- Studio: render escaped inline math in lists by @Imagineer99 in #9796
- deprecate unsupported custom prompt templates by @vineethsaivs in #8938
- Restore UNSLOTH_RETURN_LOGITS after prediction_step instead of forcing it to 0 by @danielhanchen in #6239
- Studio: update in the background and restart when ready by @NilayYadav in #9890
- Serve every MiniMax H3 asset from unsloth rather than a community repack by @danielhanchen in #8832
- fix(studio): gate external tool nudges and preserve retry context by @Biotrioo in #9125
- Chat: let the LoRA compare rehydrate a pair the generalized compare saved by @lonexreb in #9908
- fix: expose codex apply_patch for local models (#9114) by @Biotrioo in #9121
- Fix duplicate GGUF rows in custom model folders by @Imagineer99 in #9975
- Revert "fix(studio): gate external tool nudges and preserve retry context" by @danielhanchen in #9990
- studio: isolate mcp browser test state by @mahiatlinux in #9951
- Fix three CI regressions: code-span anchor, load-dispatch anchor, recordless pip install by @danielhanchen in #9959
- studio: fix audio ci tests by @mahiatlinux in #9953
- studio: fix openai route ci tests by @mahiatlinux in #9952
- Skip the inline-code mask when every backtick is inside a fence by @danielhanchen in #9991
- stop the planner withholding a split reserve from one card, and price physical cores by @danielhanchen in #9863
- Parse the downloaded model mapper instead of exec'ing it by @danielhanchen in #9777
- Recapture the control leg reference against the fixed loss normalisation by @danielhanchen in #9569
- Stop os.dup2 alone being a reverse shell, and allowlist the zoo URL guard by @danielhanchen in #9994
- Give the in-venv CLI tests a writable STUDIO_HOME by @danielhanchen in https://github.com/unslothai/unsloth/pull...
Contributors
Assets 7
Qwen3.8-Flash-Next + GLM-5.3-Flash
Qwen3.8-Flash-Next and GLM-5.3-Flash can now run locally in Unsloth!
- Run Qwen3.8-Flash on 75GB RAM, GLM-5.3-Flash on 102GB RAM+VRAM
- 5x Faster inference for RAM offloading
- "Infinite" repeated compaction now works
- 100+ chat, reliability and performance improvements
Qwen Guide: https://unsloth.ai/docs/models/qwen3.8-next
Qwen GGUFs: https://huggingface.co/unsloth/Qwen3.8-Flash-Next-GGUF
GLM Guide: https://unsloth.ai/docs/models/glm-5.3-flash
GLM GGUFs: https://huggingface.co/unsloth/GLM-5.3-Flash-GGUF
Highlights
- Qwen3.8-Flash-Next on 75GB RAM
- GLM-5.3-Flash on 102GB total memory
- Smarter GPU + RAM offloading - run larger models with less setup
- Chats recover after disconnects instead of losing the reply
- See what fits before loading with clearer memory estimates
Qwen3.8-Flash-Next
Qwen3.8-Flash-Next is a new 125B multimodal reasoning model and an early preview of Qwen4's architecture.
- The 1-bit Unsloth Dynamic GGUF runs on 75GB RAM or unified memory.
- It's 79% smaller than BF16 while retaining 80% top-1 accuracy.
- Chat with text and images using up to 262K context.
- Switch between None, Low, Medium and Extra High reasoning.
- Preserved Thinking keeps reasoning consistent across longer chats.
GLM-5.3-Flash
GLM-5.3-Flash is Z.ai's new 320B multimodal model, with only 18B parameters active at a time.
- Run the 1-bit model on 102GB of combined RAM + VRAM.
- Chat with text, images and long documents using up to 1M context.
- Switch between Low, High and Max reasoning.
- Stronger coding, agent and vision performance than GLM-5.2.
- Recommended settings are applied automatically in Unsloth.
Chat + tools
- Local chats resume after a disconnect instead of losing the reply.
- Deep Research keeps going when a provider asks it to slow down.
- Vision chats now handle multiple images properly.
- Images returned by MCP tools appear directly in chat.
- Export chats as JSONL for backups or use in other tools.
- Adjust Auto Compaction for longer chats, or turn it off.
- Collapse tool activity by default for cleaner agent chats.
Models + performance
- Large GGUFs automatically split across GPU and system RAM.
- See estimated memory usage before loading a model.
- View VRAM usage directly from your downloaded models.
- Model settings stay saved when switching chats.
- Search and download embedding models directly from Hugging Face.
- Text-to-speech models only load when you actually use them.
Desktop + reliability
- Linux voice recording fixed.
- NVIDIA + Wayland interface freezes fixed.
- AMD model loading crashes fixed.
- llama.cpp models now load from Windows profiles with non-English characters.
- Non-English web links now work properly as chat sources.
- Desktop download links always point to the latest stable release.
What's Changed
- Bump install.sh / install.ps1 pin to unsloth>=2026.8.21 by @danielhanchen in #9699
- fix(studio): resolve PowerShell by absolute path in the update gate by @yzxcj797 in #9452
- Prevent shared preview loads from evicting the active Studio model by @NilayYadav in #7104
- studio: harden lockfile audit followups for #5604 by @danielhanchen in #5695
- Fix Linux voice recording by capturing raw PCM where WebKitGTK's MediaRecorder produces no audio by @Fizza-Mukhtar in #9564
- Studio: take remend 1.3.1, which stops repairing markdown that is already complete by @danielhanchen in #9667
- CLI: follow model reasoning default in unsloth start by @shimmyshimmer in #9733
- Name the encoding when the poll probe writes its artifact by @danielhanchen in #9691
- studio: add a freeze report script for Linux desktop interface hangs by @danielhanchen in #9668
- Fail the mac tab-capability smoke on a backend that never comes back, not on a stall by @danielhanchen in #9711
- Warm the app before timing /api/health, instead of widening the ceiling by @danielhanchen in #9724
- docs: remove duplicate Search bullet and fix error messages by @lxcxjxhx in #9566
- Follow up #9435: restore the rest of the moved names, and read quant labels through the variant lister by @danielhanchen in #9701
- Studio: use --load-mode none when the model fits without paging by @danielhanchen in #9565
- Studio: spill weights with -ot instead of layers, so the KV cache stays on the GPU by @danielhanchen in #9675
- Reject a negative chunking stride instead of silently dropping text by @vineethsaivs in #9249
- Studio: fix web pages with non-English URLs failing to load by @NilayYadav in #9721
- Studio: align composer and research activity icons by @shimmyshimmer in #9755
- desktop: turn webkit compositing off on the one wayland nvidia setup that freezes by @danielhanchen in #9734
- studio: keep a resumed turn's provider metadata through the continuation merge by @danielhanchen in #9684
- Studio: render MCP images returned as embedded resources by @NilayYadav in #9636
- Studio: send the most recent chat image to vision models by @NilayYadav in #9638
- Studio: align sidebar list header actions, and mark downloaded models with a dot by @shimmyshimmer in #9740
- Prevent stale hydration from overwriting remembered model settings by @alkinun in #9767
- Handle invalid Krea2 model indexes clearly by @alkinun in #9760
- Studio: track API token usage in Profile by @Etherll in #9320
- Studio: tell the model which documents are attached by @NilayYadav in #9718
- Studio: use live trending GGUFs in agent setup by @shimmyshimmer in #9752
- studio: preserve gguf settings across chat switches by @mahiatlinux in #9562
- studio: add message jsonl export by @mahiatlinux in #9614
- Validate studio_install_id before baking it into the launcher by @danielhanchen in #9741
- studio: show lm studio model names in chat by @mahiatlinux in #9556
- Studio: fix per-chat settings and fork counts for app-created chats by @NilayYadav in #9639
- studio: show the train run preview as a column on a laptop window by @mahiatlinux in #9762
- Use Unsloth for bare Studio product references by @shimmyshimmer in #9732
- Studio: stop the temporary toggle tagging a saved app-created chat by @danielhanchen in #9771
- Studio: honour forced tool_choice on local GGUF tool loops by @Souravrajvi0 in #9773
- Desktop: publish stable latest downloads by @oobabooga in #9652
- Give every installing job its own pip cache key by @danielhanchen in #9781
- Studio: report confirmed explicit GGUF context by @Doud-FR in #9713
- Studio: keep Deep Research alive when the provider asks it to slow down by @NilayYadav in #9720
- Studio: don't silently drop extra images from a message by @NilayYadav in #9719
- Studio: hide model disclaimer by default by @shimmyshimmer in #9789
- README: drop the Linux (Arm64) download row, which serves a macOS file by @danielhanchen in #9783
- studio: newline-terminate exported jsonl records by @mahiatlinux in #8759
- Take
pytest tests/from 16m22s to 4m17s at -n 16 by @danielhanchen in #9794 - Derive the fp8 fbgemm test tolerance from the bf16 ULP by @danielhanchen in #9795
- Make importing unsloth.models._utils twice in a process survive by @danielhanchen in #9793
- Studio: let the model decide when a message needs Deep Research by @NilayYadav in #9726
- Fix GGUF mmproj pairing for derivative repos by @Imagineer99 in #6574
- Remove duplicate TRL vLLM generation patch by @alkinun in #9764
- Studio: widen what the offload planner can place instead of declining by @danielhanchen in #9778
- Studio: turn the offload planner on by default by @danielhanchen in #9779
- studio: add a sampling seed to the chat run settings by @mahiatlinux in #9144
- Return no base model, not the bare
unsloth/org, for a timest...
Contributors


Assets 8
Bug Fixes + Auto compaction + LAN Remote Access
Thanks for the support for Qwen3.8-27B and Unsloth Desktop! This is a bug fix release with 170+ PRs.
- MLX fixed - Some MLX and Mac runtimes did not run correctly
- LAN API keyless / password-less + Keyboard shortcuts
- XET / HTTP download toggle - clearer download progress
- AMD bug fixes + 170 bug, reliability & performance fixes
Features
- Auto Compaction (Experimental) for longer chats beyond context limits
- Remote & LAN Access (Preview) for easy network access without Cloudflare links
- Faster Chat - Improved streaming performance, reduced UI lag, and smoother long conversations.
- Support for custom llama.cpp builds. Toggles for Cache RAM, Mmap, Mlock, Checkpoints, Spe Decoding KV Cache, Vision On / Off
- Unsloth Dynamic v3.0 is released. New Qwen3.8-27B Dynamic v3.0 GGUFs deliver >10% higher top-1 accuracy compared to everyone else. Works with Unsloth.
Auto compaction (Experimental)
You can now do long chats and surpass a model's context limit, with evicted turns
remaining searchable.
- Long local chats can continue past the context limit by rolling older turns out of
active context. - Auto compaction creates fresh context epochs instead of permanently trimming replies.
- Evicted conversations remain searchable, with improved fact recall.
- Context window information is shown before chat begins.
How it works
- Entire oldest turns are removed only when needed, never mid-message. The saved transcript stays unchanged.
- Evicted turns are indexed into a per-thread searchable archive using Unsloth's existing RAG pipeline (store, chunker, embedder, retrieval). Lexical search is prioritized because chat recall is usually exact matches like names, numbers, or IDs.
- A recall is forced during eviction instead of relying on the model to search itself. Later retrieval uses
search_conversation. - The archive persists across epochs, allowing future compactions to recover previously evicted context.
- No summarization: it showed little benefit and added ~190s per compaction.
Remote & LAN access (Preview)
Access Unsloth from another device on your network, managed from settings.
- New dedicated Settings section for remote access.
- Enable or disable LAN access without restarting.
- Supports connection addresses, QR codes, and optional auto-start.
- LAN access is disabled by default and requires changing the generated admin password.
Chat + Functionality improvements
- Long chats are faster with optimized streaming and thread handling.
- Projects organize chats, files, and workspaces together.
- Chats remember composer settings, system prompts, and model sampling options.
- Added prompt queueing and customizable keyboard shortcuts.
- Added
edit_filetool for partial file modifications. - Improved tool calling and MCP behavior.
Hardware + inference improvements
- Support for custom llama.cpp builds.
- Toggles for advanced settings - Cache RAM, Mmap, Mlock, Checkpoints, Speculative Decoding KV Cache, Vision On / Off
- Better validation for missing GPU support and oversized GGUF models.
- Improved MTP performance and VRAM handling.
- Better compatibility across ROCm, xFormers, and flash-attention setups.
- Added Intel XPU support.
API + serving
- Responses API supports structured output formatting.
- Improved recovery when llama-server crashes.
- Added OpenCode V2 support for
unsloth start.
Hub + Desktop + training
- Hub supports more image/video workflows.
- Faster and improved GGUF downloads.
- Desktop packaging and permissions improved.
- Training scheduler and preprocessing improvements.
What's Changed
- Bump install.sh / install.ps1 pin to unsloth>=2026.8.19 by @danielhanchen in #9422
- Say what killed a UI wrapper script instead of reporting a bare 143 by @danielhanchen in #9407
- Fix stale libappindicator3-dev guard blocking desktop releases by @danielhanchen in #9426
- studio: drag and drop files onto project sources and knowledge bases by @mahiatlinux in #9147
- Read a llama install's ggml tree from its release when the marker lacks one by @danielhanchen in #7912
- studio: add custom stt connections by @mahiatlinux in #9349
- Repair the two studio test suites #9410 left behind by @danielhanchen in #9437
- CI: hold the Anthropic SDK below 1.0 in the inference smoke workflows by @danielhanchen in #9432
- studio: collapse the reasoning pane with grid rows instead of a measured height, behind a flag by @danielhanchen in #9423
- Studio: turn on the sidebar drag's scoped custom-property writes by @danielhanchen in #9441
- Studio: re-ask the projector placement after a tensor-parallel downgrade by @danielhanchen in #9408
- Studio: hide the Tensor Parallelism switch on diffusion models by @danielhanchen in #9418
- Exclude the imatrix from the local models route too by @danielhanchen in #9411
- Studio: fall back to the legacy --swa-checkpoints spelling by @danielhanchen in #9416
- Retry the desktop ownership id read that a concurrent publish denies by @danielhanchen in #9459
- Bound the SDK majors CI installs, and guard the ones the probes call by @danielhanchen in #9460
- Stop the chart metric formatters truncating values of 1000 and up by @vineethsaivs in #8724
- Studio: queue media generation behind model teardown by @divagr18 in #8866
- Studio: keep server chats visible when legacy IndexedDB stalls by @oobabooga in #9446
- fix(studio): rewind the MLX PRNG in the KV quantization probe without item assignment by @Lyxot in #9478
- install: fetch managed Python when distro uv.toml sets downloads=manual by @gokay-ai in #9358
- Studio: admit GGUFs that fit carved-out Vulkan UMA by @alkinun in #9461
- Studio: settings nav badges and the Shortcuts icon by @shimmyshimmer in #9497
- studio: stop a menu dismissal deleting a chat message by @mahiatlinux in #9243
- Unwedge Backend CI: one deadlocked test, and a timer that names the next one by @danielhanchen in #9515
- Studio: copy a thread selection without building the styled clipboard flavour by @danielhanchen in #9457
- Studio: turn on the grid-based reasoning collapse by @danielhanchen in #9511
- Studio: defer off-screen code fence highlighting, one way only by @danielhanchen in #9462
- studio: measure the code block collapse the thread override prevents by @danielhanchen in #9464
- Studio: accept .ods files from drag and drop by @Etherll in #9455
- open every attachment type in a preview modal by @mahiatlinux in #8655
- Import the OpenDocument MIME constants from where they are exported by @danielhanchen in #9520
- Studio: don't let MCP training kill a live chat stream by @NilayYadav in #9434
- Desktop: attach dropped source files on desktop instead of refusing them by @NilayYadav in #9495
- Studio: avoid AppImage COLRv1 font crashes by @wasimysaid in #9473
- Studio: stop an unterminated code fence re-repairing itself on every chunk by @danielhanchen in #9517
- Studio: list the other embedding models, and show Documents & RAG in Data by @shimmyshimmer in #9514
- Studio: document reasoning on the Agents tab, and add --reasoning-effort by @shimmyshimmer in #9513
- Bound the backend pytest session so a wedged xdist worker cannot eat the job by @danielhanchen in #9530
- Studio: paint a long thread's newest messages immediately instead of rebuilding all of them first by @danielhanchen in #9058
- Allowlist the remote-server locale keys in the desktop branding sweep by @danielhanchen in #9529
- Give the Studio T4 leg a Kaggle client that can read its own credential by @danielhanchen in #9535
- Assert the event-loop property directly in the two load_freeze latency tests by @danielhanchen in #9532
- studio: stream event feeds over post by @mahiatlinux in #9533
- Studio: stop the KV starvation message reading as a context limit on the client by @danielhanchen in #9417
- Studio: measure a dense tool result instead of estimating it, and never raise a configured cap by @danielhanchen in https://github.com/unslothai/unsloth/pull/...
Contributors


Assets 8
Bug Fixes + Auto compaction + LAN Remote Access
Thanks for the support for Qwen3.8-27B and Unsloth Desktop! This is a bug fix release with 170+ PRs.
- MLX fixed - Some MLX and Mac runtimes did not run correctly
- LAN API keyless / password-less is now supported
- XET / HTTP download toggle - clearer download progress
- AMD bug fixes for Strix Halo, all RDNA GPUs + 170 bug fixes
Features
- Auto Compaction (Experimental) for longer chats beyond context limits
- Remote & LAN Access (Preview) for easy network access without Cloudflare links
- Faster Chat - Improved streaming performance, reduced UI lag, and smoother long conversations.
- Support for custom llama.cpp builds. Toggles for Cache RAM, Mmap, Mlock, Checkpoints, Spe Decoding KV Cache, Vision On / Off
- Unsloth Dynamic v3.0 is released. New Qwen3.8-27B Dynamic v3.0 GGUFs deliver >10% higher top-1 accuracy compared to everyone else. Works with Unsloth.
Auto compaction (Experimental)
You can now do long chats and surpass a model's context limit, with evicted turns
remaining searchable.
- Long local chats can continue past the context limit by rolling older turns out of
active context. - Auto compaction creates fresh context epochs instead of permanently trimming replies.
- Evicted conversations remain searchable, with improved fact recall.
- Context window information is shown before chat begins.
How it works
- Entire oldest turns are removed only when needed, never mid-message. The saved transcript stays unchanged.
- Evicted turns are indexed into a per-thread searchable archive using Unsloth's existing RAG pipeline (store, chunker, embedder, retrieval). Lexical search is prioritized because chat recall is usually exact matches like names, numbers, or IDs.
- A recall is forced during eviction instead of relying on the model to search itself. Later retrieval uses
search_conversation. - The archive persists across epochs, allowing future compactions to recover previously evicted context.
- No summarization: it showed little benefit and added ~190s per compaction.
Remote & LAN access (Preview)
Access Unsloth from another device on your network, managed from settings.
- New dedicated Settings section for remote access.
- Enable or disable LAN access without restarting.
- Supports connection addresses, QR codes, and optional auto-start.
- LAN access is disabled by default and requires changing the generated admin password.
Chat + Functionality improvements
- Long chats are faster with optimized streaming and thread handling.
- Projects organize chats, files, and workspaces together.
- Chats remember composer settings, system prompts, and model sampling options.
- Added prompt queueing and customizable keyboard shortcuts.
- Added
edit_filetool for partial file modifications. - Improved tool calling and MCP behavior.
Hardware + inference improvements
- Support for custom llama.cpp builds.
- Toggles for advanced settings - Cache RAM, Mmap, Mlock, Checkpoints, Speculative Decoding KV Cache, Vision On / Off
- Better validation for missing GPU support and oversized GGUF models.
- Improved MTP performance and VRAM handling.
- Better compatibility across ROCm, xFormers, and flash-attention setups.
- Added Intel XPU support.
API + serving
- Responses API supports structured output formatting.
- Improved recovery when llama-server crashes.
- Added OpenCode V2 support for
unsloth start.
Hub + Desktop + training
- Hub supports more image/video workflows.
- Faster and improved GGUF downloads.
- Desktop packaging and permissions improved.
- Training scheduler and preprocessing improvements.
What's Changed
- Bump install.sh / install.ps1 pin to unsloth>=2026.8.19 by @danielhanchen in #9422
- Say what killed a UI wrapper script instead of reporting a bare 143 by @danielhanchen in #9407
- Fix stale libappindicator3-dev guard blocking desktop releases by @danielhanchen in #9426
- studio: drag and drop files onto project sources and knowledge bases by @mahiatlinux in #9147
- Read a llama install's ggml tree from its release when the marker lacks one by @danielhanchen in #7912
- studio: add custom stt connections by @mahiatlinux in #9349
- Repair the two studio test suites #9410 left behind by @danielhanchen in #9437
- CI: hold the Anthropic SDK below 1.0 in the inference smoke workflows by @danielhanchen in #9432
- studio: collapse the reasoning pane with grid rows instead of a measured height, behind a flag by @danielhanchen in #9423
- Studio: turn on the sidebar drag's scoped custom-property writes by @danielhanchen in #9441
- Studio: re-ask the projector placement after a tensor-parallel downgrade by @danielhanchen in #9408
- Studio: hide the Tensor Parallelism switch on diffusion models by @danielhanchen in #9418
- Exclude the imatrix from the local models route too by @danielhanchen in #9411
- Studio: fall back to the legacy --swa-checkpoints spelling by @danielhanchen in #9416
- Retry the desktop ownership id read that a concurrent publish denies by @danielhanchen in #9459
- Bound the SDK majors CI installs, and guard the ones the probes call by @danielhanchen in #9460
- Stop the chart metric formatters truncating values of 1000 and up by @vineethsaivs in #8724
- Studio: queue media generation behind model teardown by @divagr18 in #8866
- Studio: keep server chats visible when legacy IndexedDB stalls by @oobabooga in #9446
- fix(studio): rewind the MLX PRNG in the KV quantization probe without item assignment by @Lyxot in #9478
- install: fetch managed Python when distro uv.toml sets downloads=manual by @gokay-ai in #9358
- Studio: admit GGUFs that fit carved-out Vulkan UMA by @alkinun in #9461
- Studio: settings nav badges and the Shortcuts icon by @shimmyshimmer in #9497
- studio: stop a menu dismissal deleting a chat message by @mahiatlinux in #9243
- Unwedge Backend CI: one deadlocked test, and a timer that names the next one by @danielhanchen in #9515
- Studio: copy a thread selection without building the styled clipboard flavour by @danielhanchen in #9457
- Studio: turn on the grid-based reasoning collapse by @danielhanchen in #9511
- Studio: defer off-screen code fence highlighting, one way only by @danielhanchen in #9462
- studio: measure the code block collapse the thread override prevents by @danielhanchen in #9464
- Studio: accept .ods files from drag and drop by @Etherll in #9455
- open every attachment type in a preview modal by @mahiatlinux in #8655
- Import the OpenDocument MIME constants from where they are exported by @danielhanchen in #9520
- Studio: don't let MCP training kill a live chat stream by @NilayYadav in #9434
- Desktop: attach dropped source files on desktop instead of refusing them by @NilayYadav in #9495
- Studio: avoid AppImage COLRv1 font crashes by @wasimysaid in #9473
- Studio: stop an unterminated code fence re-repairing itself on every chunk by @danielhanchen in #9517
- Studio: list the other embedding models, and show Documents & RAG in Data by @shimmyshimmer in #9514
- Studio: document reasoning on the Agents tab, and add --reasoning-effort by @shimmyshimmer in #9513
- Bound the backend pytest session so a wedged xdist worker cannot eat the job by @danielhanchen in #9530
- Studio: paint a long thread's newest messages immediately instead of rebuilding all of them first by @danielhanchen in #9058
- Allowlist the remote-server locale keys in the desktop branding sweep by @danielhanchen in #9529
- Give the Studio T4 leg a Kaggle client that can read its own credential by @danielhanchen in #9535
- Assert the event-loop property directly in the two load_freeze latency tests by @danielhanchen in #9532
- studio: stream event feeds over post by @mahiatlinux in #9533
- Studio: stop the KV starvation message reading as a context limit on the client by @danielhanchen in #9417
- Studio: measure a dense tool result instead of estimating it, and never raise a configured cap by @danielhanchen in #9...
Contributors
Assets 8
Auto compaction (preview) + LAN Remote Access

Thanks for the support for Qwen3.8-27B and Unsloth Desktop last week! For this release, we merged 200+ PRs to introduce many new features, fixes including:
- Auto Compaction (Experimental) for longer chats beyond context limits
- Remote & LAN Access (Preview) for easy network access without Cloudflare links
- Faster Chat - Improved streaming performance, reduced UI lag, and smoother long conversations.
- Support for custom llama.cpp builds. Toggles for Cache RAM, Mmap, Mlock, Checkpoints, Spe Decoding KV Cache, Vision On / Off
- Unsloth Dynamic v3.0 is released. New Qwen3.8-27B Dynamic v3.0 GGUFs deliver >10% higher top-1 accuracy compared to everyone else. Works with Unsloth.
Auto compaction (Experimental)
You can now do long chats and surpass a model's context limit, with evicted turns
remaining searchable.
- Long local chats can continue past the context limit by rolling older turns out of
active context. - Auto compaction creates fresh context epochs instead of permanently trimming replies.
- Evicted conversations remain searchable, with improved fact recall.
- Context window information is shown before chat begins.
How it works
- Entire oldest turns are removed only when needed, never mid-message. The saved transcript stays unchanged.
- Evicted turns are indexed into a per-thread searchable archive using Unsloth's existing RAG pipeline (store, chunker, embedder, retrieval). Lexical search is prioritized because chat recall is usually exact matches like names, numbers, or IDs.
- A recall is forced during eviction instead of relying on the model to search itself. Later retrieval uses
search_conversation. - The archive persists across epochs, allowing future compactions to recover previously evicted context.
- No summarization: it showed little benefit and added ~190s per compaction.
Remote & LAN access (Preview)
Access Unsloth from another device on your network, managed from settings.
- New dedicated Settings section for remote access.
- Enable or disable LAN access without restarting.
- Supports connection addresses, QR codes, and optional auto-start.
- LAN access is disabled by default and requires changing the generated admin password.
Chat + Functionality improvements
- Long chats are faster with optimized streaming and thread handling.
- Projects organize chats, files, and workspaces together.
- Chats remember composer settings, system prompts, and model sampling options.
- Added prompt queueing and customizable keyboard shortcuts.
- Added
edit_filetool for partial file modifications. - Improved tool calling and MCP behavior.
Hardware + inference improvements
- Support for custom llama.cpp builds.
- Toggles for advanced settings - Cache RAM, Mmap, Mlock, Checkpoints, Speculative Decoding KV Cache, Vision On / Off
- Better validation for missing GPU support and oversized GGUF models.
- Improved MTP performance and VRAM handling.
- Better compatibility across ROCm, xFormers, and flash-attention setups.
- Added Intel XPU support.
API + serving
- Responses API supports structured output formatting.
- Improved recovery when llama-server crashes.
- Added OpenCode V2 support for
unsloth start.
Hub + Desktop + training
- Hub supports more image/video workflows.
- Faster and improved GGUF downloads.
- Desktop packaging and permissions improved.
- Training scheduler and preprocessing improvements.
| Platform | Link |
| Windows | Download |
| macOS | Download |
| Linux / Ubuntu (deb) | Download |
| Linux (AppImage) | Download |
| Linux (Arm64) | Download |
What's Changed
- Bump install.sh / install.ps1 pin to unsloth>=2026.8.18 by @danielhanchen in #8836
- Give the llama-flag fixtures the parallelSlotsClamped they now require by @vineethsaivs in #8837
- Studio: preserve pre-tool reasoning inside the GGUF tool loop by @losuler in #8581
- docs: fix dead Linux .deb download link by @yzxcj797 in #8891
- Model hub: show the Meta mark on the Unsloth re-upload of Muse Glimmer by @shimmyshimmer in #8949
- Studio: speed up the local model inventory and keep it off the API loop by @oobabooga in #8770
- Studio: reuse the cached GGUF work a load request has already done by @oobabooga in #8771
- studio: keep each tool-call round separate when the delta index restarts by @mahiatlinux in #8754
- studio: route bare tool-call fragments to the call that owns the index now by @mahiatlinux in #8755
- studio: opt-in model auto-switch for the image and video apis by @mahiatlinux in #8766
- Studio: keep project chats in Recents, add a Projects sidebar section by @shimmyshimmer in #8932
- Studio: find the real Documents folder on Windows for project workspaces by @shimmyshimmer in #8955
- fix(unsloth studio): only preprocess the rows a max_steps run will actually use instead of preprocessing validated datasets by @LeoBorcherding in #8890
- Studio: stop the chat UI falling behind a fast stream by @oobabooga in #8845
- studio: keep each chat's composer pills and settings with the chat by @mahiatlinux in #8686
- studio: allow a per-connection max tokens limit on every provider by @mahiatlinux in #8944
- Crash guard: read dumpability in order, and stop losing crashes to scope and naming by @danielhanchen in #8808
- Studio: size the max_steps row bound for the data-parallel world by @danielhanchen in #8958
- Studio: make the paste-to-attachment threshold a chat setting by @shimmyshimmer in #8963
- Fix CI on main: stale test doubles, a stale router stub, and two source defects by @danielhanchen in #8956
- Make the startup profile a gate, with budgets from its own measurements by @danielhanchen in #8965
- Keep xFormers working when flash-attn 4 is installed, and guard the varlen int32 overflow by @danielhanchen in #8957
- Stop six backend tests waiting on the clock instead of on a signal by @danielhanchen in #8975
- CI: stop three workflows paying for work they throw away by @danielhanchen in #8976
- Give the pasted-text import an extension so the node test runner can load it by @danielhanchen in #8981
- Make the packed-boundary guard reachable on the fused cross-entropy path by @danielhanchen in #8959
- Studio: Fix embedded MTP performance under partial GPU offload by @oobabooga in #8875
- Studio: tokenize the dataset online for plain-text single-pass runs by @danielhanchen in #8960
- Studio: keep K and V equal when the flash-attention retry resets the V cache by @danielhanchen in #8827
- Studio: hold the Auto-layers context exemption only while --fit runs by @danielhanchen in #8825
- Studio: stop a sent prompt staying in the chat composer by @shimmyshimmer in #8849
- Chat: queue prompts with Cmd/Ctrl+Enter and drag to reorder the queue by @shimmyshimmer in #8952
- Studio: repin the permission-mode contract to behaviour, not a declaration by @danielhanchen in #8986
- Cut Repo tests (CPU) roughly in half: stop the synthetic vLLM tests reaping a fake server by @danielhanchen in #8993
- Core: sweep every transformers model_type across a process pool by @danielhanchen in #8995
- Repair the Tauri retry test against the download-marker pipeline by @danielhanchen in #8996
- Studio: read every launcher world size when resolving a step-capped run's passes by @danielhanchen in #9000
- Repair the prompt-queue contract test against the queueing refactor by @danielhanchen in #9026
- studio: stop prom...
Contributors


Assets 8
Qwen3.8-27B
Qwen3.8-27B and Qwen3.8-2.4T can now be run locally in Unsloth!
Run on 17GB RAM via Unsloth Dynamic GGUFs. You can also fine-tune Qwen3.8-27B in Unsloth.
Qwen3.8-27B is by far the strongest model for its size. We also uploaded NVFP4 quants.
Guide: https://unsloth.ai/docs/models/qwen3.8
GGUF: https://huggingface.co/unsloth/Qwen3.8-27B-GGUF
See 1-bit Qwen3.8-2.4T GGUF running in Unsloth:

Highlights
- Qwen3.8-27B + extra llama-server arguments allowed + custom VRAM toggle
- External provider has tool calling + tool support + login with Codex
- Fast FP8 10x faster MiniMax-H3 inference (3 minutes vs 30)
- 10% faster inference for GGUFs + Bypass permissions fixed
Chat + tools
- Connected AI providers can use their own Search or Unsloth Desktop's built-in Search and tools. Tool results are passed back to the model so it can continue multi-step tasks.
- Sign in with a Codex subscription and use Codex tools inside Chat.
- Chat shows live prompt and generation speeds, while long streaming replies use much less CPU.
- Chat settings stay with the conversation across remote sessions.
- Paste a YouTube link to attach its transcript, including the title, channel, duration, link, and caption language.
- Save a full chat or reply into your project's sources while keeping its reasoning, tool calls, and citations.
MiniMax-H3
- MiniMax-H3 can run on smaller supported GPUs by splitting large model parts into pieces that fit.
- The model picker now hides H3 options that the current hardware cannot run instead of letting them fail after selection.
- H3 options are labelled Fast FP8 or Slow, making the large speed difference clear before downloading.
Performance + hardware
- Inference is up to 10% faster in supported cases, with lower VRAM use and a tunable memory limit.
- Idle image and video models can optionally unload to free VRAM for Chat or Training.
- Added better support for AMD RDNA 3, RDNA 4, and Strix Halo systems. VRAM checks no longer reserve extra GPU memory.
- Multi-GPU ROCm device matching is safer.
- Macs now choose context size from the memory that is actually free.
- RAG document indexing uses the CPU by default, so it no longer leaves a large GPU memory block reserved.
- Fixed GGUF image detection when choosing a model for the API.
Custom llama.cpp arguments
- Model settings now include an Extra Arguments box for custom
llama-serverflags. - Unsloth checks flags against the installed build and saves valid ones per model for normal, startup, and API loads. Flags that could break model loading or app security are rejected with a clear message.
Training + exports
- Training checks whether a model needs a newer Transformers version and asks before installing it. The preview also tells you when the model must use 16-bit instead of 4-bit.
- GGUF exports check disk space before starting a long merge, with clearer errors showing how much space is needed.
- On Kaggle, large saves can use the bigger temporary drive when the working folder is too small.
- Fixed LoRA being ignored by vLLM GRPO rollouts on newer TRL versions.
Debugging + reliability
- Settings > Debugging now shows the main server and model-runner logs, with live, 3-second, and manual refresh modes.
- Copy the visible log or its full path for a bug report. Passwords, tokens, and API keys are hidden in the viewer, while files on disk stay unchanged.
- Cached RAG models load first, avoiding long stalls when Hugging Face is unreachable.
- Slow installs can keep running during large downloads and show what they are waiting for.
- Fixed Hugging Face dataset links and linked folders on Windows.
- Pinned models can be reordered by dragging them in the model list.
Download Unsloth Desktop
Unsloth Desktop is free and open source. Download it for:
- Windows
- macOS
- Linux
What's Changed
- Bump install.sh / install.ps1 pin to unsloth>=2026.8.14 by @shimmyshimmer in #8455
- Point the Images rail contract at the in-flow footer padding by @danielhanchen in #8446
- GRPO: dispatch on width at the remaining lm_head matmul call sites by @danielhanchen in #8204
- Studio: let repair proceed past a backend that is not ours by @danielhanchen in #8459
- Studio: keep the download rail in the corner under the welcome composer by @danielhanchen in #8462
- Studio: keep prose that documents call:NAME{...} in the answer by @danielhanchen in #8437
- Studio: name the checkpoint on MiniMax H3 quant chips by @danielhanchen in #8466
- Stop the PowerShell progress bar throttling installer downloads to 0.65 MB/s by @danielhanchen in #8476
- Windows installer: fix single-AMD-GPU detection and the unrecoverable "needs repair" loop by @danielhanchen in #8398
- Studio: ask macOS for zombie status with the flavor that answers by @danielhanchen in #8484
- Auto mode: ask before PyYAML deserialization that can run code by @danielhanchen in #8432
- Drop the inert capacity-sweeper dispatch from the desktop release by @danielhanchen in #8477
- Windows: fix single-AMD-GPU hosts reading as "gpu none" and looping the installer by @danielhanchen in #8461
- Installer: suppress macOS uv developer tools dialog by @wasimysaid in #8479
- Bump install.sh / install.ps1 pin to unsloth>=2026.8.15 by @danielhanchen in #8491
- Read macOS zombie status from sysctl, the call that answers by @danielhanchen in #8493
- Studio: remove obsolete onboarding and model code by @wasimysaid in #8453
- Studio: stop building test scratch paths inside a macOS sensitive root by @danielhanchen in #8485
- CI: run the Studio desktop unit tests on macOS by @danielhanchen in #8487
- Studio: keep the compiled cache when a sibling backend is live by @danielhanchen in #8457
- Drop socket reads that arrive after an h11 connection is closed by @danielhanchen in #8469
- Studio: name a connected model the provider dropped instead of its raw id by @danielhanchen in #8470
- Studio: classify a moved or mixed model folder from the checkpoint, not from directory order by @danielhanchen in #8475
- Route spoofed Strix Halo GPUs to the AMD per-gfx index by @danielhanchen in #8480
- Studio: report host VRAM usage when no single GPU's usage can be attributed by @danielhanchen in #8481
- Studio: stop the memory guards trusting an over-reported free VRAM on Windows ROCm by @danielhanchen in #8482
- Studio: give the tool-call strip one owner and one scan order by @danielhanchen in #8427
- Studio: stop rescanning the whole answer on every streamed token by @danielhanchen in #8538
- Studio: cut backend start time and stop blocking the event loop by @danielhanchen in #8498
- Studio backend performance: five superlinear paths in the routes and data layer by @danielhanchen in #8499
- Studio: read ?model= from the diffusion page's own route match by @NilayYadav in #8260
- Install torchao in Backend CI, and stop one test's allowlist answer leaking into the rest by @danielhanchen in #8486
- Clear the four main CI reds blocking every open PR by @danielhanchen in #8506
- Studio: drop the duplicated HubModelPicker import in model-selector by @danielhanchen in #8534
- Studio: drop a duplicate import that breaks the frontend build by @danielhanchen in #8553
- Unsloth Studio: add ChatGPT subscription chat with Codex tools by @wasimysaid in #8511
- Pin sha256 hashes for triton-xpu 3.6.0 wheels in intelgputorch210 by @danielhanchen in #8543
- security: lockfile audit must block non-registry sources and missing integrity by default by @danielhanchen in #8541
- Studio: verify the flash-attn import after installing it by @danielhanchen in #8465
- Studio: finish the backend CI cleanup #8506 started by @danielhanchen in #8554
- Studio: linear-time tool signal scanning in the safetensors and healer paths by @danielhanchen in #8494
- Studio: only a UI session may define a local (stdio) MCP command by @danielhanchen in #8550
- studio: fa...
Contributors


Assets 8
v0.1.702-beta
Unsloth Desktop is here! The first desktop app to run and train AI models locally. Research, export and deploy from the same open-source app on Windows, macOS and Linux.
v0.1.702-beta Update (August 13th)
- Added tool calling / web search & more for all external providers
- Fixed bypass permissions not working for sandboxing
- UI and UX fixes - VRAM usage is now tunable
- 10% faster inference + reduced VRAM usage and other perf fixes
- Much better AMD RDNA3,4 + Strix Halo, Mac support
- Image diffusion, video generation fixes
- Can login with Codex subscription
- Many bug fixes
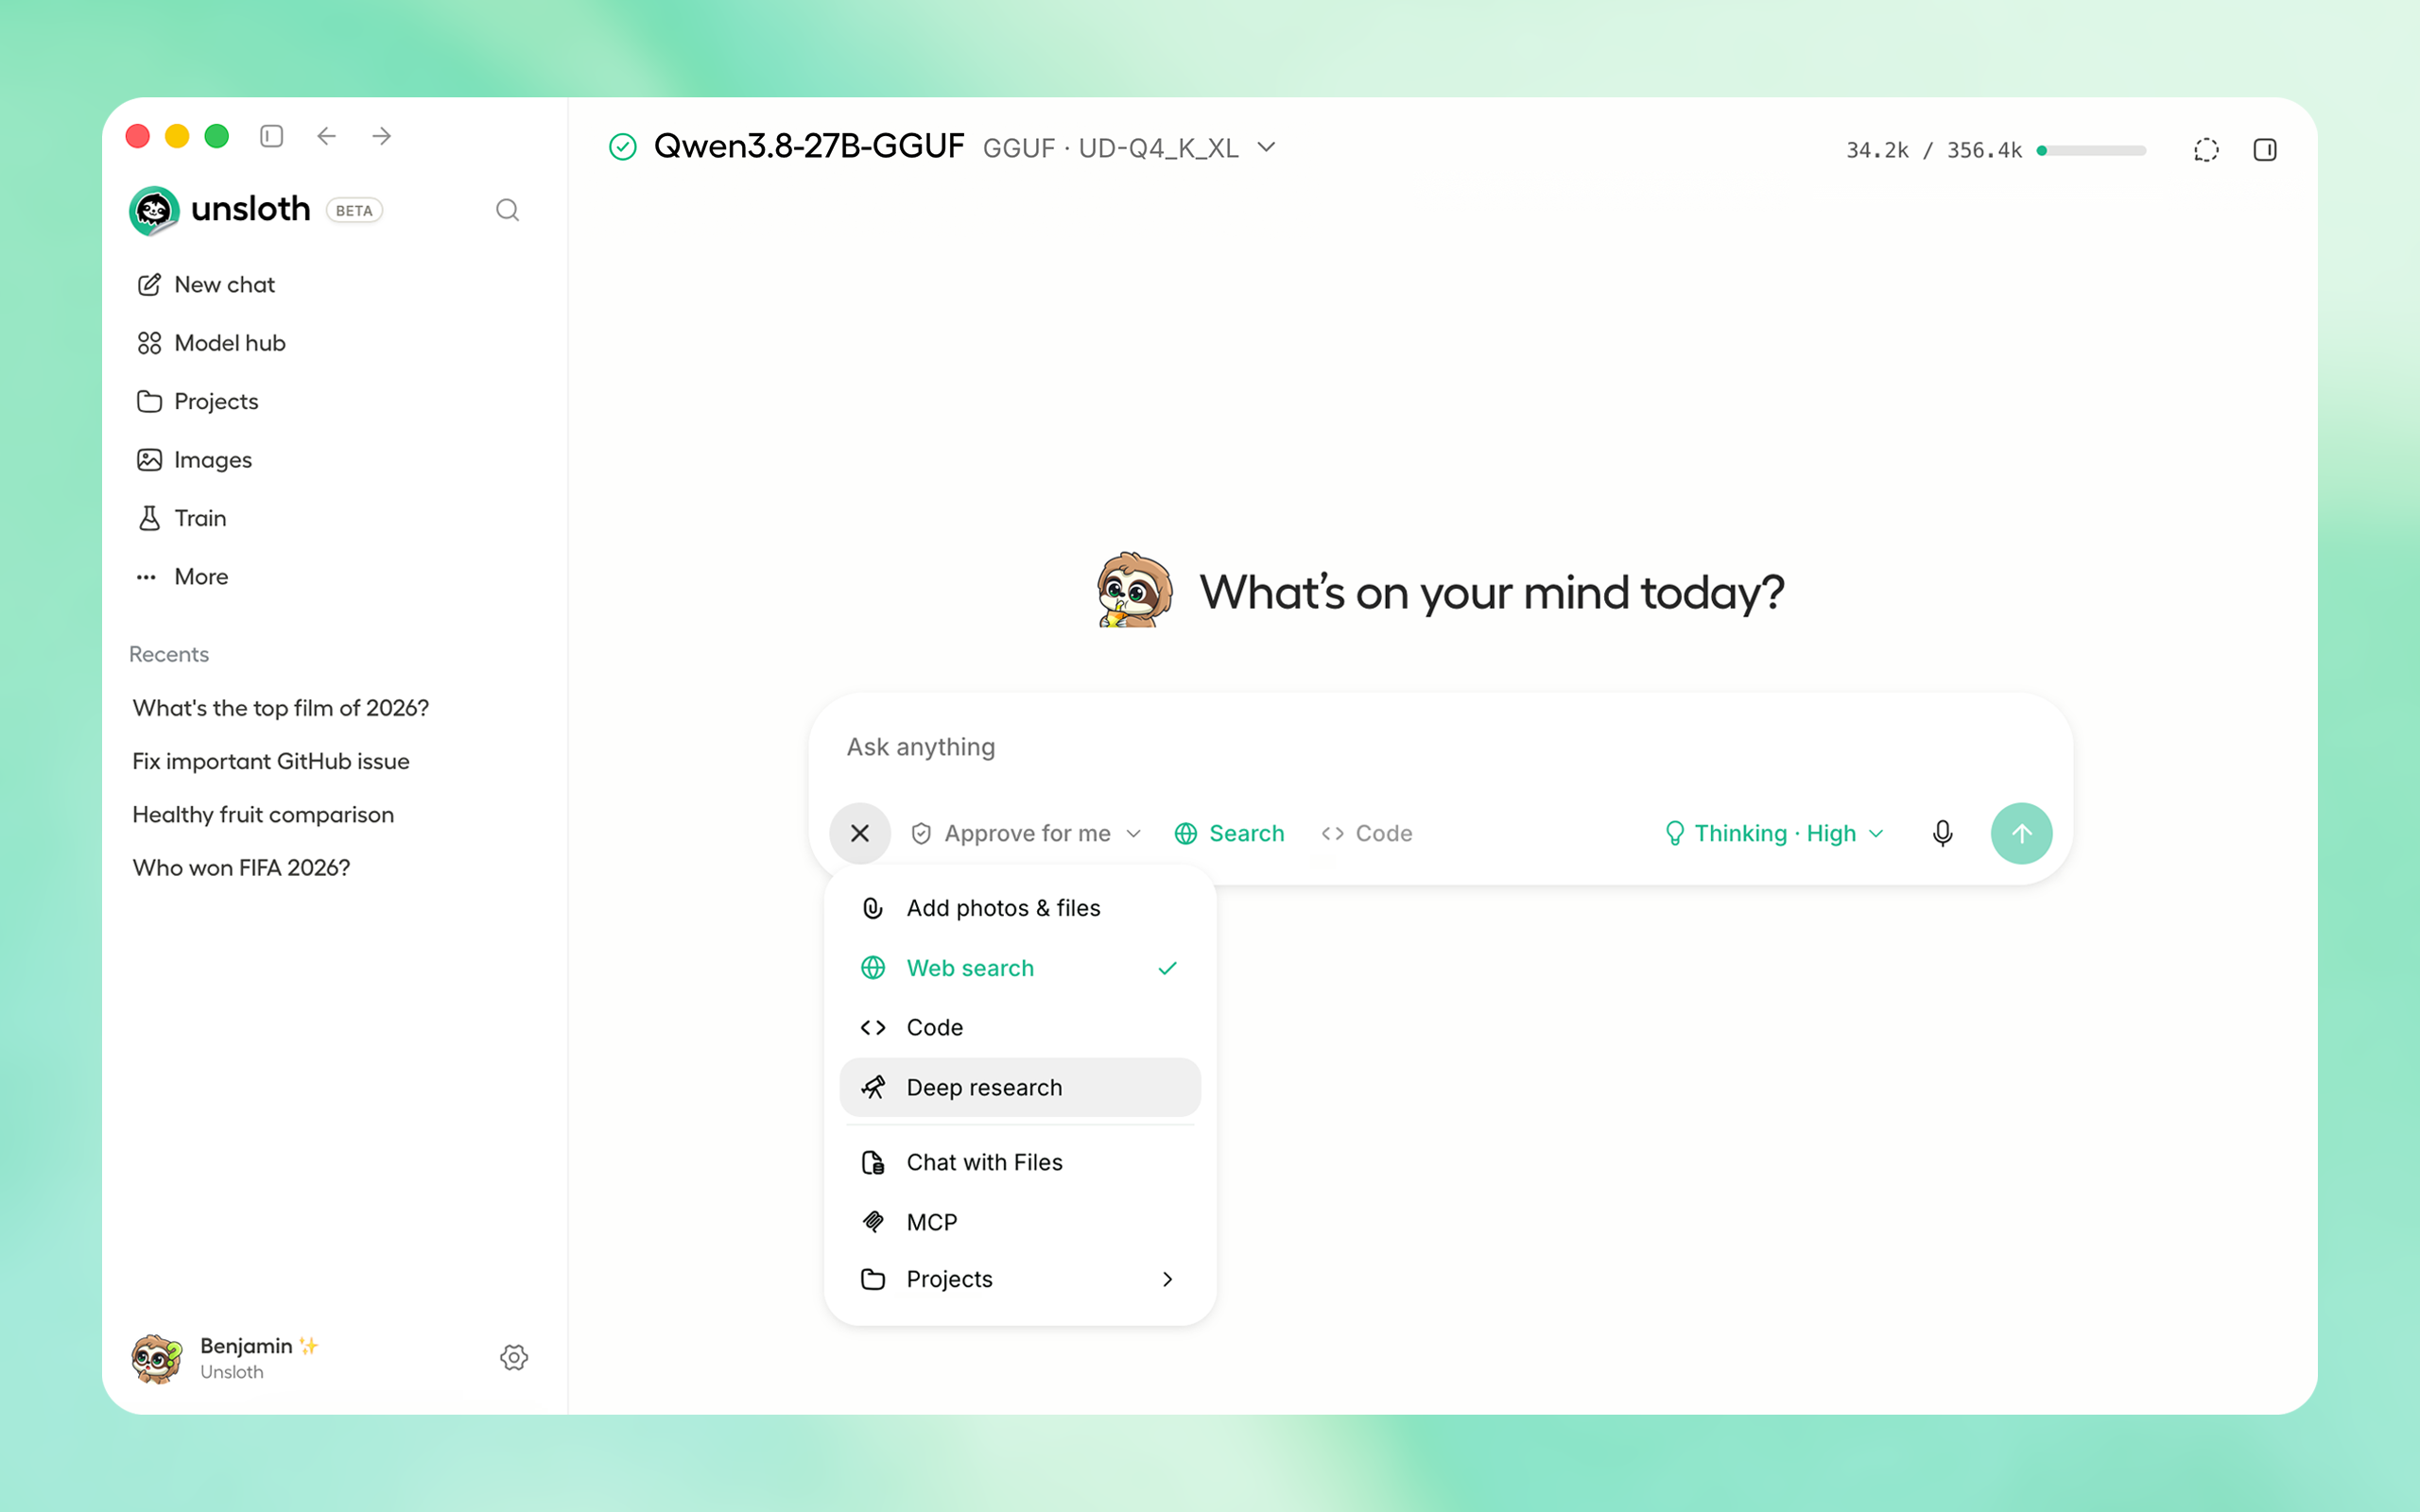
🦥 Download Unsloth Desktop for Linux, Windows, MacOS
Here's what you can do with Unsloth Desktop:
- Get up to 50% more accurate tool calling with self-healing calls and sandboxed code execution.
- Run Muse Glimmer 30B, Kimi K3, Qwen3.8, DeepSeek-V4 Flash 0731, Gemma 4, and more.
- Generate videos with MiniMax-H3, and create images and videos with other diffusion models at up to 2× faster inference on supported workflows.
- Use unlimited private web search, Deep Research, RAG and MCP.
- Export models to NVFP4, GGUF and other formats.
- Access Unsloth remotely through Cloudflare HTTPS.
- Run on CPU or multiple GPUs across NVIDIA, AMD, Intel and Mac.
- Train models without code, using less time and VRAM.
- Use local models through Unsloth's OpenAI-compatible API, or connect OpenAI and Anthropic models.
Tools, private research + APIs
Self-healing tool calling repairs malformed calls instead of dropping them. Models can run Python and Bash inside sandboxed environments, so they can test code, create files and verify their work.
Use unlimited private web search, let Deep Research plan and produce cited reports, or bring your own files into RAG. You can also connect MCP tools for workflows that need external apps, data or actions.
Local models can be served through Unsloth's OpenAI-compatible API for agents and other clients. Inside Desktop, you can also connect OpenAI and Anthropic as cloud model providers.
Muse Glimmer 30B + latest models
Run Muse Glimmer 30B locally for chat, agents, tools and APIs, alongside Kimi K3, Qwen3.8, DeepSeek-V4 Flash 0731 and Gemma 4. Download and manage them in one place through Unsloth Desktop.
MiniMax-H3 + image and video diffusion
Run MiniMax-H3 locally for video generation. Create images and videos locally, edit existing images and train supported diffusion models. Use LoRAs, reference images and ControlNet where available, with up to 2× faster inference on supported workflows.
No-code training, export + remote deployment
Pick a model and dataset, adjust the settings and start training. You can train supported LLMs, diffusion models, TTS models and embedding models without writing code. On supported LLM workloads, training is up to 2× faster and uses up to 70% less VRAM.
Export your trained models to NVFP4, GGUF and other supported formats. You can also securely deploy and access models remotely: turn on Remote access to publish Unsloth through a Cloudflare HTTPS link, then use the app and its local APIs from another device.
Hardware + platform support
Unsloth Desktop runs on Windows, macOS and Linux. Hardware support spans CPU and multi-GPU systems, NVIDIA and AMD GPUs, Intel hardware, and Mac.
CPU support includes Chat and Data Recipes. Training and inference options vary by model and backend.
Download Unsloth Desktop
Unsloth Desktop is free and open source. Download it for:
- Windows
- macOS
- Linux
v0.1.701-beta Update (1PM PDT time August 11th)
- Fixed slow Windows downloading (200x faster due to throttling)
- Fixed Mac asking to download command line tools (uv bug)
- Fixed AMD Strix Halo not being detected
- Other bug fixes