Skip to content

feat(core): add a convergence reminder for read-only exploration - #13601

Open
yiliang114 wants to merge 2 commits into
QwenLM:mainfrom
yiliang114:codex/feedback-loop-convergence
Open

yiliang114 wants to merge 2 commits into
QwenLM:mainfrom
yiliang114:codex/feedback-loop-convergence

Conversation

@yiliang114

@yiliang114 yiliang114 commented Oct 7, 2026 •

Copy link
Copy Markdown
Collaborator

What this PR does

Adds one advisory reminder when a continuous phase of registered read, search, or fetch calls reaches the existing tool-call allowance. The next model continuation asks the agent to use the gathered information, advance the requested deliverable or explain a concrete blocker; a read-only investigation is asked to summarize findings and remaining questions. Core CLI and daemon/ACP loops share the same small budget implementation.

Planning, implementation, delegation, and unknown tool kinds reset the exploration phase. Registry-declared MCP tools and bridged tool calls use their registered kind. Retries roll back uncommitted observations, duplicate provider call IDs count once, and logical-turn resets clear the core budget.

Why it's needed

Diverse successful reads can pass the default adaptive allowance without producing a deliverable. The existing cap protects against repeated calls and provides a hard backstop, but it does not ask the agent to consolidate its investigation at the soft threshold. This adds that checkpoint without making an advisory message look like a failed turn.

Reviewer Test Plan

How to verify

Run a read-only task with distinct real file reads past the unchanged adaptive allowance. Confirm one reminder is included after the tool results, one additional legitimate read still executes, and the model can finish with a read-only summary. Repeat through the ordinary daemon/ACP Session path. Confirm planning or implementation resets the phase, disabled allowances produce no reminder, and a provider retry cannot duplicate a previously delivered reminder.

Evidence (Before & After)

Before: distinct read-only discovery passes the adaptive threshold without a convergence reminder. After: local native CLI and ordinary daemon/ACP evidence is attached in a separate verification comment, including actual tmux captures, outgoing provider messages, real tool results, and executed source/build identities.

At historical bb78e71ffb54e884b50f2044e63978a8e92bee26, 649 core tests and 12 focused Session tests passed; 1,181 filtered CLI cases were not executed. Core/CLI builds, typechecks and targeted lint/format checks passed at that head. At current 2525fee66359cd06211e48f7ee06982c2b5043d2, CLI build/typecheck, 56 client-goal tests and two selected cap/duplicate Session tests passed; 1,153 other Session cases were not executed. The current-head additional productive control completed 99 real reads, a separate successful summary creation, then two verification reads, with no exploration reminder and exact output bytes. No build or unit rerun was needed for this native control.

Tested on

OS Status
🍏 macOS ✅ Local package checks; native acceptance report attached separately
🪟 Windows ⚠️ Not tested locally
🐧 Linux ⚠️ Not tested locally

Environment

Local built CLI and ordinary daemon/ACP Session, anonymous owned fixtures, and a controlled OpenAI-compatible provider. Native runs exercise real tool execution; controlled model responses validate reminder mechanics and continued tool availability.

Risk & Scope

  • Main risk or tradeoff: the reminder adds an advisory instruction at the exploration threshold. A model may ignore it; tool kind is a conservative phase signal, not proof of semantic progress or successful execution.
  • Not validated / out of scope: historical downstream deployment reproduction, production-model convergence or token savings, and the separate repeated-failure rollout policy in [core] No early termination on repeated tool errors: sessions burn 5-14M tokens in dead-end loops #10887.
  • Breaking changes / migration notes: none. Existing adaptive and explicit hard caps, plan approval, and tool permissions remain authoritative; no write is forced and no new halt or terminal loop event is emitted. Disabled/infinite allowances produce no reminder, and the core explicit loop-detector disable suppresses it. Older manually constructed daemon loop states without the optional budget retain their previous behavior.

Design: English · 简体中文. Both versions contain matching decisions, constraints, acceptance criteria, and open boundaries.

Linked Issues

Addresses #13321. This PR delivers the advisory convergence checkpoint; it does not claim a deterministic semantic-completion guarantee.

中文说明

此 PR 的改动

当一段连续的已注册读取、搜索或抓取调用达到现有工具调用 allowance 时,追加一次建议性提醒。下一轮模型续跑会要求利用已收集的信息,推进用户要求的交付物或解释具体阻塞;如果用户要求只读调查,则要求总结发现和剩余问题。Core CLI 与 daemon/ACP 循环共享同一个小型计数器实现。

规划、实现、委派和未知工具类型会重置探索阶段。MCP 工具以及桥接调用按 registry 中声明的 kind 分类。重试会回滚未提交的观察结果,重复的 provider 调用 ID 只计一次,逻辑回合重置会清空 core 计数器。

为什么需要

参数多样的成功读取可能越过默认自适应 allowance,却没有产生交付物。现有上限限制重复调用并提供最终兜底,但不会在软阈值处要求模型汇总调查。这次补充该检查点,并保持提醒的建议性质,避免把它呈现为失败回合。

Reviewer Test Plan

如何验证

使用参数不同的真实文件读取,让只读任务越过未修改的自适应 allowance。确认工具结果之后只有一次提醒,再执行一次合理读取仍然成功,模型可以自然结束并给出只读总结。对普通 daemon/ACP Session 路径重复验证。确认规划或实现会重置阶段、禁用 allowance 不产生提醒,provider 重试不会重复投递已交付的提醒。

证据(Before / After)

Before:不同参数的只读探索越过自适应阈值时没有收敛提醒。After:独立验证评论附上本地真实 CLI、普通 daemon/ACP 证据,包括实际 tmux capture、发往 provider 的消息、真实工具结果和执行源码/构建身份。

历史 bb78e71ffb54e884b50f2044e63978a8e92bee26 的 649 项 core、12 项定向 Session 测试及 core/CLI 构建、类型和定向 lint/格式检查通过;另有 1,181 项过滤的 CLI 用例未执行。当前 2525fee66359cd06211e48f7ee06982c2b5043d2 的 CLI 构建/类型、56 个 client-goal 和两个定向 cap/重复调用 Session 测试通过,其他 1,153 项 Session 用例未执行。当前 head 的新增实际写入控制报告完成 99 次真实读取、独立汇总创建和两次验证读取,无探索提醒,输出字节准确;本次原生控制无需重复构建或单测。

测试平台

OS 状态
🍏 macOS ✅ 本地包检查;原生验收报告单独附在评论中
🪟 Windows ⚠️ 未在本地验证
🐧 Linux ⚠️ 未在本地验证

环境

本地已构建 CLI、普通 daemon/ACP Session、匿名自有夹具和受控 OpenAI-compatible provider。原生运行执行真实工具;受控模型响应验证提醒机制和工具仍可继续使用。

风险与范围

  • 主要风险或取舍:提醒在探索阈值处增加建议性指令。模型可能忽略它;工具 kind 只是保守的阶段信号,不代表已证明语义进展或执行成功。
  • 未验证 / 不在范围内:历史下游部署复现、生产模型收敛或 token 节省,以及 [core] No early termination on repeated tool errors: sessions burn 5-14M tokens in dead-end loops #10887 的独立重复失败上线策略。
  • 不兼容改动 / 迁移说明:无。现有自适应和显式硬上限、计划审批、工具权限继续生效;不强制写入,不增加 halt 或终止性 loop 事件。禁用或无限 allowance 不产生提醒,core 的显式 loop-detector disable 也抑制提醒。旧调用方手动构造 daemon 循环状态且没有可选 budget 时保持此前行为。

设计:English · 简体中文。中英两版的决策、约束、验收标准和开放边界完整对应。

关联 Issue

关联 #13321。本 PR 实现建议性收敛检查点,不声称提供确定性的语义完成保证。

Share an advisory exploration allowance across core and daemon tool loops without adding a halt or changing tool permissions.

Co-authored-by: Qwen-Coder <[email protected]>
@qwen-code-review-bot

qwen-code-review-bot commented Oct 7, 2026 •

Copy link
Copy Markdown
Collaborator

✅ Qwen Triage finished — view run. See the stage comments in this thread for the result.

✅ Qwen Triage 已完成 —— 查看运行。结果见本线程中的各阶段评论。

@yiliang114

Copy link
Copy Markdown
Collaborator Author

#13321 native acceptance: read-only exploration reminder

PASS for both actual supported paths: headless core CLI and ordinary daemon/ACP Session. Both executed 102 real anonymous file reads, inserted one exploration reminder after the initial 101 results, accepted the additional read, and completed naturally. This controlled-provider run verifies runtime mechanics and wire insertion; it does not demonstrate production-model semantic convergence or token savings.

Candidate: bb78e71ffb54e884b50f2044e63978a8e92bee26 (source hashes verified against the committed files), based on 464f486e20198f7f39623f3e95f51ab5d4f98e40. The source and executed JavaScript hashes below were captured before and after the two native runs and were unchanged. The additive commit and normal push changed no source/build bytes. Core and CLI package builds completed with exit 0.

Actual scenarios and observations

Each isolated profile left model.maxToolCallsPerTurn unset, exercising the default adaptive allowance of 100. The anonymous loopback OpenAI-compatible provider first returned 101 distinct structured read_file calls for owned files, then returned one additional specific read (102), then a natural-stop summary. Files were served through the actual native tools, not injected as mock tool results. Each file contained 19 exact bytes, ANONYMOUS_READ_NNN plus newline; 1,938 actual bytes were checked per path against all 102 provider-received results. Local telemetry independently recorded 102 unique native call IDs with function_name=read_file, success=true, and execution_status=success per path.

Actual path Main provider requests Auxiliary provider requests First reminder boundary Final result
Core headless CLI 3 1 managed-memory Request 2: 101 exact file results; reminder at message index 104, after last tool result index 103 CLI exit 0, success, 3 turns, no permission denials
Ordinary daemon/ACP Session 3 1 managed-memory; 1 suggestion Request 2: same 101-result boundary and reminder position turn_complete/end_turn, idle, no turn error; 102 completed tool updates

Indices are zero-based wire-message indices. The reminder is a user-role text message beginning System:. In request 3, all 102 exact results were present, and the same single reminder remained at index 104; the latest tool result was at index 106. No second reminder was appended during this continuous read-only phase. read_file remained advertised in both continuation requests, and call 102 executed successfully. No write tool was issued or executed, and this reminder introduced no halt in these scenarios. The initial 101-call batch can pass the adaptive allowance before the continuation reminder; this is a soft reminder rather than an explicitly configured 100-call hard cap.

The provider records classify managed-memory by its actual managed memory extraction subagent system prompt and suggestion by the actual [SUGGESTION MODE: request. The main continuation counts exclude those requests. They replay prior history, including the existing reminder; their copies do not establish a second main-chat reminder insertion. Actual purpose/timestamp receipts are retained in result.json and original provider bodies.

Final answer in both paths:

ANONYMOUS_READONLY_FINDINGS: 102 anonymous files read successfully; remaining verification gap resolved. Controlled mechanics evidence only.

Executed-byte identity

The read-only Node load hook delegated to the normal loader and recorded actual load paths and SHA-256 values without transforming source. Core loaded its own candidate budget/client/CLI modules. The daemon loaded those modules plus its own candidate Session.js in the real ACP child process. Module loading alone is not the execution proof: the real tool results and outgoing reminder boundary establish the reached behavior.

Source or executed candidate file SHA-256 (stable before/after)
packages/core/src/services/tool-exploration-budget.ts ffa33a66937225f9d821b332eaeaaa8705e03686e1a7a6afac81fee88b413070
packages/core/src/core/client.ts 8a65505dca0e5d5e370385e6cc4d05e0e8fe3f5de3d70c21dcc6df85ae2d46a0
packages/cli/src/acp-integration/session/Session.ts 83285d024c8c78506149e96dcadd838bba315f3825f425fc0efac3657de28499
packages/cli/src/cli.ts f8563c416eb7a61aaf55e5a11e9a58d856af9c40e45c1cc391bc78719fe1fb6c
packages/core/dist/src/services/tool-exploration-budget.js 0b41f7d892122d3de411cfda400956d482d4d9cdfb00c3361fcc1f85b9dfa2b9
packages/core/dist/src/core/client.js f713fcd604a3607d5ae740bf33fe28b674699c35c8c0d0eb83482ed827d2915b
packages/cli/dist/src/acp-integration/session/Session.js 2ec2eb630d860195f713986e54e7f6bd69bb0e0057874fb54f5809d81a694f8d
packages/cli/dist/index.js 43c7251b6e923a9d112f6a5dd694725fcc1bcdfafd9225ad1c05dbc13981eabf
packages/cli/dist/src/cli.js 8709cd476aaa73ba0f048f7822aff563b48c55df725c3aeaf2ffd2095abc26bb

Actual tmux captures

These are excerpts from tmux capture-pane on the real owned sessions, with local paths/host prompts and UUIDs redacted, including UUIDs wrapped across terminal lines. Full raw captures remain local; complete sanitized captures are retained beside them.

Core final excerpt:

:1050}}}
{"type":"user","uuid":"<id>","session_id":"<id>","parent_tool_use_id":null,"message":{"role":"us
er","content":[{"type":"tool_result","tool_use_id":"native-core-read-102","is_er
ror":false,"content":"ANONYMOUS_READ_102\n"}]}}
{"type":"assistant","uuid":"<id>","session_id":"
<id>","parent_tool_use_id":null,"message":{"id":
"<id>","type":"message","role":"assistant","mode
l":"native-exploration-core","content":[{"type":"text","text":"ANONYMOUS_READONL
Y_FINDINGS: 102 anonymous files read successfully; remaining verification gap re
solved. Controlled mechanics evidence only."}],"stop_reason":null,"usage":{"inpu
t_tokens":1000,"output_tokens":50,"cache_read_input_tokens":0,"total_tokens":105
0}}}
{"type":"result","subtype":"success","uuid":"<id>","session_id":"<id>","is_error":false,"duratio
n_ms":491,"duration_api_ms":282,"num_turns":3,"result":"ANONYMOUS_READONLY_FINDI
NGS: 102 anonymous files read successfully; remaining verification gap resolved.
 Controlled mechanics evidence only.","usage":{"input_tokens":4000,"output_token
s":200,"cache_read_input_tokens":0,"total_tokens":4200},"permission_denials":[]}
Warning: running headless with --yolo / approval-mode=yolo and no sandbox. All t
ool calls (shell, write, edit) auto-execute at this process's privilege level. C
onfigure tools.executionSandbox on Linux or a supported legacy sandbox via --san
dbox / QWEN_SANDBOX, or set QWEN_CODE_SUPPRESS_YOLO_WARNING=1 to silence this no
tice.
[actual owned CLI exit 0]
<local-path> %

Ordinary daemon/ACP capture:

ACTUAL_DAEMON_READY pid=93311 defaultAllowanceSetting=UNSET
ACTUAL_PROMPT_ADMITTED {"promptId": "<id>", "las
tEventId": 0, "eventEpoch": "<id>"}
ACTUAL_TERMINAL {"id": 316, "v": 1, "type": "turn_complete", "promptId": "<id>", "data": {"sessionId": "<id>", "stopReason": "end_turn", "promptId": "<id>", "branchPoint": {"assistantRecordUuid": "<id>", "checkpointUuid": "<id>"}}, "origina
torClientId": "client_<id>", "_meta": {"serverTi
mestamp": 1791376830120}}
ACTUAL_NATIVE_DONE events=316 state={"sessionId": "<id>", "workspaceCwd": "<owned-fixture> /dae
mon/workspace", "createdAt": "2026-10-07T12:40:28.453Z", "updatedAt": "2026-10-0
7T12:40:30.120Z", "clientCount": 1, "hasActivePrompt": false, "activeWorkState":
 "idle", "hasRunningBackgroundTasks": false, "isWaitingForPermission": false, "i
sWaitingForUserQuestion": false, "pendingInteractionCount": 0, "hasTurnError": f
alse, "pendingInteractions": []}
OWNED_DAEMON_STOPPED
<local-path> %

Scope and evidence

The provider and daemon were anonymous loopback fixtures. The core used the real noninteractive stream-json CLI. The daemon used real workspace-runtime admission, session creation, prompt HTTP admission, ACP Session execution, and its SSE event stream. The profile enabled automatic approval for the owned read-only fixture. Actual user auth and configuration were untouched. No production-model reasoning, deployment policy, user-input preemption, or write/permission boundary was claimed from these two positive runs.

Productive-phase/reset/permission/disabled/retry controls were not additional native scenarios here. Local check receipts confirm 649 focused core budget/loop/client tests passing and 12 executed CLI Session tests passing; 1,181 CLI tests were skipped, including all 38 reducer cases. Those targeted-check results are separate evidence from the native observations.

The first tmux launch passed non-executable owned shell scripts directly and exited before any product process or provider request. It was corrected to invoke those scripts with /bin/zsh -f; each actual native scenario then ran once. A postprocessing parser was corrected to accept null assistant content, using the same retained records; no native rerun occurred.

Evidence is under the owned 13321-native directory: identity-before.json, identity-after.json, result.json, frozen-fixture.json, and cleanup.json; per-path original and sanitized provider requests, provider response receipts, stdout/stderr, module-load logs, local telemetry, actual tmux captures, exact anonymous file manifests, and executed settings snapshots. The daemon additionally retains actual HTTP receipts, SSE events, and final idle status. No artifacts reconstruct terminal output.

Cleanup complete: both scenario tmux sessions and provider session removed; owned provider/daemon listeners closed; no owned native process remains; owned profile/runtime/workspace directories removed. Anonymous input manifests, controlled-provider/helper snapshots, raw evidence and sanitized captures remain. No product source, Git/GitHub, dependency or build action was performed by this verifier.

中文说明

两个真实运行路径均通过:headless core CLI 与普通 daemon/ACP Session 各实际读取 102 个匿名文件,前 101 个工具结果之后的下一次主请求均只出现一条探索提醒。随后第 102 次真实读取仍正常执行;再下一次主请求包含全部 102 个精确结果,只保留原有提醒,没有追加第二条。core 正常退出 0;daemon 收到 turn_complete/end_turn 后进入 idle,未发生 turn error。工具 telemetry 和 ACP 完成事件分别佐证了真实读取,不是把预期结果直接塞入请求。

配置没有显式设置 100 次硬上限,使用现有默认自适应 allowance。此次观测证明提醒在真实运行时正确插入、工具仍可继续使用且未被强迫写入或新增 halt。模型回复来自受控匿名本地 provider,因此不能据此声称生产模型一定收敛、减少 token 或产生有效研究结论。managed-memory 与 suggestion 的辅助请求按实际请求标记区分,它们携带历史中的同一条提醒,不计为主会话的再次插入。

运行前后源码与实际加载 JS 的 SHA-256 均一致,源码哈希已与完整候选 commit 中的文件核对。报告保留实际 tmux 抓取及脱敏版本,连跨行折断的 UUID 一并脱敏。所有自有 provider、daemon、tmux、临时 profile/runtime/workspace 已清理;原始请求、事件、telemetry、捕获和匿名输入清单保留。权限、重试及 reset 等边界以本地定向测试为独立证据,本报告没有扩大为第三次 native 场景,也没有声称执行被跳过的 CLI 测试。

@qwen-code-review-bot

qwen-code-review-bot commented Oct 7, 2026 •

Copy link
Copy Markdown
Collaborator

Thanks — re-running the gate at the current head 2525fee6, which is a different commit from the pass that deferred at bb78e71f. The follow-up commit is additive and I reviewed the code as it now stands.

Template looks good ✓ — every heading from the template is present and filled in, including Evidence (Before & After) and Risk & Scope.

Problem: the mechanism gap is real and I verified it on main rather than taking the description's word for it. getMaxToolCallsPerTurn() returns the configured value, or Infinity when it is <= 0, and the adaptive default only halts a diverse-call turn on a stuck-repetition signal or at the hard backstop (shouldHaltOnTurnToolCallCap, loopDetectionService.ts:212). So a turn of 100 distinct successful reads passes the soft allowance with nothing asking the model to consolidate. What is not established is the user-level harm: #13321 is still open, carries need-discussion, and records one historical session (~9.6M tokens, no deliverable) whose deployed version was never captured and which was never reproduced on main. The PR says so plainly in its own scope section, which is the honest way to present it. This is a feat, so the missing reproduction is a direction question, not a Stage 1b blocker.

Direction: in scope, and more in-idiom than I expected from the description. Runaway-exploration bounding is already shipped policy here (adaptive cap, hard backstop, LoopDetectionService, #10887), and the advisory-reminder-at-a-threshold shape is already shipped too — the new reminder lands in the same parts array directly beside REPEATED_TOOL_FAILURE_REMINDER (Session.ts:9331) and beside activeTodoReminder on the core side. This extends an accepted mechanism rather than opening a new product surface. The genuine product question is narrower than "should this exist": it is whether an advisory nudge is worth its tokens when its effectiveness on production models is unmeasured. That question was escalated on the previous pass and is parked with @DragonnZhang plus the five requested reviewers; nothing here re-opens it.

Size: core paths are touched (packages/core/src/core, packages/core/src/services, packages/cli/src/acp-integration), so the two-tier gate applies. Breakdown of the 333 added lines, 0 deleted: 140 production (tool-exploration-budget.ts 80, client.ts 32, Session.ts 24, loopDetectionService.ts 4), 139 test (tool-exploration-budget.test.ts 88, Session.test.ts 46, client-goal.test.ts 5), 54 docs (the two design docs). 140 is well under the 500-line escalation threshold and this is a feat, so no size-based escalation and no hard block. Tier 2's confidence bar is the one that matters, and I could name every downstream consumer — listed in the review comment.

Approach: scope feels right and the diff is genuinely minimal — zero deletions, no drive-by refactor, no formatting churn, no unrelated files. Both design docs are present with reciprocal language links and matching section structure, which is what AGENTS.md asks for. I considered hosting the counter inside LoopDetectionService to inherit its existing reset hooks, but the daemon cannot use that class, and the repo already solves exactly this problem the way this PR does: a small pure helper in core imported by both runtimes (shouldHaltOnTurnToolCallCap is defined in loopDetectionService.ts:212, exported from core, and imported at Session.ts:194). So the extracted-module shape follows precedent rather than inventing a parallel one. Nothing I would cut.

Risk: Stage 1e matched one high-risk path — packages/cli/src/acp-integration/session/Session.ts (acp-integration). That is the revert-correlated signal, not a defect, but it raises review depth: no enrichment skipped, CI evidence required before approval, and a sandboxed lane named for the behavioural claim. Both are in the review comment.

Moving on to code review. 🔍

中文说明

感谢贡献 —— 本次在当前 head 2525fee6 重新过闸,与上次给出 defer 的 bb78e71f 不是同一个 commit。后续 commit 是纯增量的,我按现在的代码重新审查。

模板完整 ✓ —— 模板要求的每个标题都在且填写了,包括 Evidence (Before & After) 和 Risk & Scope。

**问题:**机制缺口是真实的,我在 main 上核实过,没有只采信 PR 描述。getMaxToolCallsPerTurn() 返回配置值,<= 0 时返回 Infinity;自适应默认只在出现重复卡死信号或触到硬兜底时才停(shouldHaltOnTurnToolCallCap,loopDetectionService.ts:212)。所以一轮 100 次参数各异的成功读取可以越过软阈值,而没有任何东西要求模型收敛。未成立的是用户层面的损害:#13321 仍处于 open,带 need-discussion,只记录了一次历史会话(约 9.6M token、无交付物),当时部署版本没有留档,也未在 main 上复现。PR 在自己的 scope 段落里如实说明了这点。这是 feat,所以缺少复现属于方向问题,不是 Stage 1b 的阻断项。

**方向:**在范围内,而且比描述读起来更贴合本仓库既有做法。约束失控探索在这里已经是既定策略(自适应上限、硬兜底、LoopDetectionService、#10887),"在阈值处插入建议性提醒"这个形态也已经在跑 —— 新提醒就落在同一个 parts 数组里,紧挨着 REPEATED_TOOL_FAILURE_REMINDER(Session.ts:9331),core 侧则紧挨着 activeTodoReminder。这是扩展一个已被接受的机制,不是开辟新的产品面。真正的产品问题比"该不该有"更窄:在效果未经生产模型测量时,这条建议性提醒值不值得它占用的 token。这个问题上一轮已经上报,现在停在 @DragonnZhang 和五位被请求的 reviewer 那里,本次没有重新翻开它。

**规模:**触及核心路径(packages/core/src/core、packages/core/src/services、packages/cli/src/acp-integration),两级闸门适用。333 行新增、0 行删除的构成:生产代码 140 行(tool-exploration-budget.ts 80、client.ts 32、Session.ts 24、loopDetectionService.ts 4)、测试 139 行(tool-exploration-budget.test.ts 88、Session.test.ts 46、client-goal.test.ts 5)、文档 54 行(两份设计文档)。140 远低于 500 行的上报阈值,且类型是 feat,因此不按规模上报、也不硬阻断。真正起作用的是 Tier 2 的信心门槛,我能点名每一个下游消费者 —— 列在代码审查评论里。

**方案:**范围合理,diff 确实最小化 —— 零删除、没有顺手重构、没有格式抖动、没有无关文件。两份设计文档都在,带互相指向的语言链接且章节结构对应,符合 AGENTS.md 的要求。我考虑过把计数器放进 LoopDetectionService 以复用现有 reset 钩子,但 daemon 用不了那个类;而本仓库解决同一问题的既有做法就是这个 PR 的做法:在 core 放一个小的纯函数/小类,由两个运行时共同引用(shouldHaltOnTurnToolCallCap 定义在 loopDetectionService.ts:212,从 core 导出,在 Session.ts:194 被引入)。所以抽成独立模块是沿用先例,不是另造一套。没有我想砍掉的部分。

**风险:**Stage 1e 命中一条高风险路径 —— packages/cli/src/acp-integration/session/Session.ts(acp-integration)。这是与 revert 相关的信号,不是缺陷,但会提高审查深度:不跳过任何 enrichment、批准前必须有 CI 证据、并为行为性结论点名沙箱验证通道。两者都写在代码审查评论里。

进入代码审查 🔍

— Qwen Code · qwen3.8-max-2026-09-02

Reviewed at 2525fee66359cd06211e48f7ee06982c2b5043d2 · re-run with @qwen-code /triage

@qwen-code-review-bot

qwen-code-review-bot commented Oct 7, 2026 •

Copy link
Copy Markdown
Collaborator

Code review

No critical blockers and no AGENTS.md violations. One low-severity finding worth a one-line fix, named below.

I wrote my independent proposal before opening the diff: a counter for the continuous read-only phase, reset at logical-turn boundaries, emitting one advisory text part at the existing allowance. My first instinct was to host it inside LoopDetectionService to inherit the reset/commit/rollback hooks already wired in client.ts. That does not work, because the daemon cannot use LoopDetectionService — it keeps its own DaemonToolLoopState and shares only pure predicates with core. The repo already has a convention for exactly this, and the PR follows it: shouldHaltOnTurnToolCallCap is defined in loopDetectionService.ts:212, exported from core, and imported at Session.ts:194 so the two runtimes cannot drift. A small standalone module in core/src/services imported by both sides is the same move. The PR's shape is at least as good as mine, and it is 80 lines with four methods and no cleverness in it.

What I verified against main rather than reading for plausibility:

  • Every API the new module leans on exists with the assumed signature: Kind.Read|Search|Fetch|Edit|Think (tools/tools.ts:1309), canonicalToolName (tool-names.ts:215), resolveRegisteredToolName returning string | string[] | undefined (tool-names.ts:233) — the new code handles the array case by declining to classify, which is the right answer for an ambiguous case-insensitive registration and is pinned by a test. ToolNames.TOOL_CALL is 'tool_call', ToolRegistry.getAllToolNames() (tool-registry.ts:1479) and getTool() (:1518) match.
  • The cross-package import resolves: core's exports map carries "./*": "./dist/src/*" (packages/core/package.json:86), so @qwen-code/qwen-code-core/services/tool-exploration-budget.js lands on the built module. Importing the defining module instead of the package root is what AGENTS.md requires.
  • Reset wiring is complete. client.ts has exactly four loopDetector.reset(prompt_id) sites (3800, 4141, 5283, 5391) and the diff adds a matching budget reset at all four, so no path leaks the counter across logical turns. I checked for a fifth site; there isn't one.
  • Both insertion points are correct and preserve existing ordering. On the core side takeReminder sits inside the messageType === SendMessageType.ToolResult block (opened at client.ts:4675) and pushes before the activeTodoReminder splice runs, so findIndex now stops at the reminder and the todo reminder lands just ahead of it — still after every functionResponse part, which is what the Qwen call/response pairing constraint needs. On the daemon side the reminder goes into the single parts array (base Session.ts:9326) between activeTodoReminder and REPEATED_TOOL_FAILURE_REMINDER, ahead of drained.parts; there is only one such assembly site, so no continuation path is missed.
  • The daemon needs no rollback and correctly has none. recordDaemonToolCalls is reached only for a completed attempt — the base comment at Session.ts:1092 states that RETRY / MODEL_FALLBACK discard the failed attempt's calls before re-streaming — and the new record loop is deliberately placed after both halt checks, so a batch that would cross the cap never feeds the budget. That placement is the substance of the follow-up commit and it is right.
  • The optional field is not a dead switch. Every DaemonToolLoopState comes from createDaemonToolLoopState (call sites 6757, 7731, 10491, 11591), which always constructs the budget; the ?. guards exist for the exported type's sake, not for a live undefined path.
  • client.ts already calls config.getToolRegistry().getAllToolNames() per event at :4783, so classifying each call the same way is consistent with existing cost, and client.test.ts already mocked both accessors (:871, :954 returning Infinity) — which is why only client-goal.test.ts needed completing. That mock returns POSITIVE_INFINITY, so those tests keep their prior behaviour instead of being bent around the feature.

Finding (low severity, not a blocker): ModelFallback does not roll the budget back. client.ts:4911 groups LlmEventType.Retry and LlmEventType.ModelFallback in one branch — both clear hasToolCalls and loopGuardFedCallIds and call restartAttempt, i.e. both discard the attempt's accumulated tool calls, and both are emitted from the same place (turn.ts:760 and turn.ts:777). The new block rolls back on Retry only, so after a model fallback the budget keeps Read/Search/Fetch counts for calls that were thrown away and never executed. The reminder can then fire earlier than the true executed count within that logical turn; it self-heals at the next reset. Worst case is one advisory sentence arriving early after a fallback during a heavy read-only turn, which is why I am not calling it a blocker — but the adjacent base code and the daemon comment both treat the two events as a pair, so adding || event.type === LlmEventType.ModelFallback would make the core path match its own stated invariant.

Two things I traced and concluded are fine, mentioned so you know they were checked rather than missed. Core's record runs before checkAlwaysOnSafeties, so a batch the always-on cap then halts has already been counted — harmless, because that path clears turn.pendingToolCalls and returns, ending the logical turn. And takeReminder writes committedReminded eagerly, so a rollback after a phase-ending tool restores reminded = true and suppresses a later reminder; that is the deliberate "never duplicate a delivered reminder" tradeoff and the third unit test pins it explicitly.

Added tests genuinely pin the change rather than passing alongside it: the budget test asserts the threshold, one-shot suppression, phase resets on Edit/Think/undefined, retry rollback, disabled allowance, ambiguous registrations, and bridged MCP kinds; the Session test asserts exactly one reminder reaches the provider, that a third read still executes, and that the reminder is the last part in the follow-up message. Removing the feature would fail both.

sequenceDiagram
    participant P1 as Model stream
    participant P2 as LlmClient or Session loop
    participant P3 as ToolExplorationBudget
    participant P4 as Next provider request
    P1->>P2: ToolCallRequest events
    P2->>P3: record the resolved Kind (Read, Search, Fetch count, anything else resets the phase)
    P1->>P2: Finished or Retry
    P2->>P3: commit on Finished, rollback on Retry
    Note over P2,P3: ModelFallback also discards the attempt but does not roll back
    P2->>P3: takeReminder with the per-turn allowance, on a tool-result turn
    P3-->>P2: reminder text once, then suppressed for the phase
    P2->>P4: tool results, then the reminder text
    Note over P2,P3: reset at all four logical-turn boundaries
Loading

Testing

This is an unattended CI re-run, so per the gate rules I executed nothing from this PR — no build, no test, no gh pr checkout. The evidence below is the PR's own CI, read through the API for the reviewed commit. Real-scenario tmux testing is N/A on this path; a maintainer can trigger it (see the lane line below).

All 34 check-runs on 2525fee6 are settled: 0 failures, 0 pending, and all three pull_request workflow runs (Qwen Code CI, SDK Java, tui-parity) completed successfully. Nothing is red, so there is no failing-job log excerpt to quote. The skipped jobs — Test (macos-latest), Test (windows-latest), Integration Tests (CLI, No Sandbox), and five orchestration jobs — are skipped by the workflows' own filters, not failed. The diff is platform-independent TypeScript with no path, filesystem, process, or shell surface, so the green ubuntu unit suite plus lint plus the no-AK integration run is adequate coverage for it; the Java SDK matrix is unrelated to this diff and green regardless.

34 check-runs on the reviewed commit — 0 failure, 0 pending. Java SDK matrix grouped into one row.

Check Conclusion
Test (ubuntu-latest, Node 22.x) success
Lint & Static (ubuntu-latest, Node 22.x) success
Integration Tests (no-AK, No Sandbox) success
TUI parity snapshots (ink vs opentui) success
OpenTUI no-flicker gate success
web-shell E2E Smoke (ubuntu-latest, Node 22.x) success
Desktop Shell (ubuntu-22.04) success
Desktop Shell (windows-2022) success
precheck-pr / precheck success
Classify PR success
review-pr success
authorize success
assign / label (x2) / delay-automatic-review / Remind on force-push success
SDK Java matrix (9 jobs: ubuntu Java 11, 17, 21; macos Java 21; windows Java 21; Flyway uniqueness; MySQL 8.4 fault gates; MariaDB broker; Real daemon E2E) success
Test (macos-latest, Node 22.x) skipped
Test (windows-latest, Node 22.x) skipped
Integration Tests (CLI, No Sandbox) skipped
ack-review-request / fallback-comment / publish-resolution / resolve-pr / review-config skipped

Sandboxed verification would settle the part CI cannot: @qwen-code /verify — that on the current head the reminder is actually present in the outgoing provider request at the allowance, that one further legitimate read still executes afterwards, and that a provider retry cannot deliver it twice. The unit and Session tests pin those mechanics against mocks, and the author's own native reports are self-run against a controlled loopback provider, so no independent A/B against the base build exists yet. @qwen-code /tmux is the lane for the interactive surface, since the reminder is model-bound text a user never sees directly but which changes what the model does next. The author has write access, so both lanes are directly available.

Not verified, and why: production-model convergence and token savings — no evidence of any kind, and the PR explicitly places them out of scope, so I am treating the reminder as an unproven-but-cheap nudge rather than a demonstrated win. Also not verified: Windows and Linux runtime behaviour, which the author's own table marks untested (the diff has no platform-specific surface, so I do not consider this a gap worth blocking on). The author's tmux captures, request histories, and source-hash identities in this thread are the author's claims, not evidence I re-ran — I could not, and did not treat them as a substitute.

中文说明

代码审查

没有关键阻断项,也没有违反 AGENTS.md 的地方。有一条低严重度发现,建议一行修复,写在下面。

我在看 diff 之前先写了自己的方案:一个统计连续只读阶段的计数器,在逻辑轮次边界重置,到达现有 allowance 时输出一条建议性 text part。我最初的想法是把它放进 LoopDetectionService,复用 client.ts 里已经接好的 reset/commit/rollback 钩子。这条路走不通,因为 daemon 用不了 LoopDetectionService —— 它自己维护 DaemonToolLoopState,只和 core 共享纯判定函数。而本仓库对这个问题已有既定做法,这个 PR 正是照此办理:shouldHaltOnTurnToolCallCap 定义在 loopDetectionService.ts:212,从 core 导出,在 Session.ts:194 被引入,使两个运行时不会漂移。在 core/src/services 放一个独立小模块、两侧共同引用,是同一个套路。PR 的结构不亚于我的方案,而且 80 行、四个方法,里面没有花招。

我对照 main 核实(而不是看起来合理就放过)的内容:

  • 新模块依赖的每个 API 都存在且签名相符:Kind.Read|Search|Fetch|Edit|Think(tools/tools.ts:1309)、canonicalToolName(tool-names.ts:215)、resolveRegisteredToolName 返回 string | string[] | undefined(tool-names.ts:233)—— 新代码对数组情形选择不分类,这对"大小写不敏感的歧义注册"是正确答案,并且有测试固定。ToolNames.TOOL_CALL 是 'tool_call',ToolRegistry.getAllToolNames()(tool-registry.ts:1479)与 getTool()(:1518)相符。
  • 跨包 import 可解析:core 的 exports map 有 "./*": "./dist/src/*"(packages/core/package.json:86),所以 @qwen-code/qwen-code-core/services/tool-exploration-budget.js 指向构建产物。引入定义模块而不是包根,正是 AGENTS.md 的要求。
  • reset 接线完整。client.ts 恰好有四处 loopDetector.reset(prompt_id)(3800、4141、5283、5391),diff 在这四处都补了对应的 budget reset,因此不存在计数器跨逻辑轮次泄漏的路径。我找过第五处,没有。
  • **两个插入点都正确,且保留了既有顺序。**core 侧 takeReminder 位于 messageType === SendMessageType.ToolResult 块内(起于 client.ts:4675),push 发生在 activeTodoReminder 的 splice 之前,因此 findIndex 现在会停在提醒处,todo 提醒落在它前面 —— 仍在所有 functionResponse part 之后,满足 Qwen 的 call/response 配对约束。daemon 侧提醒进入唯一的 parts 数组(base Session.ts:9326),位于 activeTodoReminder 与 REPEATED_TOOL_FAILURE_REMINDER 之间、drained.parts 之前;这样的组装点只有一个,所以没有漏掉任何续跑路径。
  • daemon 不需要 rollback,也正确地没有加。recordDaemonToolCalls 只会为已完成的 attempt 被调用 —— base 在 Session.ts:1092 的注释明确说明 RETRY / MODEL_FALLBACK 会在重新流式之前丢弃失败 attempt 的调用 —— 而新的 record 循环刻意放在两个 halt 检查之后,所以会被上限拦掉的批次不会喂给 budget。这个位置正是后续 commit 的实质内容,放对了。
  • **可选字段不是死开关。**每个 DaemonToolLoopState 都来自 createDaemonToolLoopState(调用点 6757、7731、10491、11591),它总会构造 budget;?. 是为导出类型准备的,不是一条真实存在的 undefined 路径。
  • client.ts 在 :4783 本来就按事件调用 config.getToolRegistry().getAllToolNames(),所以按同样方式分类每次调用与既有开销一致;client.test.ts 也已 mock 了这两个访问器(:871、:954 返回 Infinity)—— 这正是只有 client-goal.test.ts 需要补全的原因。那个 mock 返回 POSITIVE_INFINITY,所以这些测试保持原有行为,而不是被掰弯去迁就新功能。

发现(低严重度,非阻断):ModelFallback 不会回滚 budget。client.ts:4911 把 LlmEventType.Retry 和 LlmEventType.ModelFallback 放在同一个分支 —— 两者都会清掉 hasToolCalls 和 loopGuardFedCallIds 并调用 restartAttempt,也就是都丢弃该 attempt 累积的工具调用,而且两者由同一处发出(turn.ts:760 与 turn.ts:777)。新增的块只在 Retry 时回滚,所以模型 fallback 之后,budget 会保留那些已被丢弃、从未执行的调用的 Read/Search/Fetch 计数。于是同一逻辑轮次内,提醒可能比真实执行次数更早触发;下一次 reset 会自愈。最坏情况是一轮大量只读调用中发生 fallback 之后,一条建议性文本提前出现 —— 这也是我没有把它判为阻断项的原因。但相邻的 base 代码和 daemon 注释都把这两个事件成对处理,所以加上 || event.type === LlmEventType.ModelFallback 能让 core 路径符合它自己声明的不变量。

另外两处我追查后认为没问题,写出来是为了让你知道它们被检查过而不是被漏掉。core 的 record 在 checkAlwaysOnSafeties 之前执行,所以被 always-on 上限拦下的批次其实已经被计入 —— 无害,因为该路径会清空 turn.pendingToolCalls 并 return,逻辑轮次随之结束。以及 takeReminder 会立即写入 committedReminded,所以在一次结束阶段的工具之后发生 rollback 会把 reminded 恢复为 true,从而抑制后续提醒;这是"绝不重复投递已发送提醒"的有意取舍,第三个单测明确固定了它。

新增测试确实固定了改动,而不是与之并行通过:budget 测试断言阈值、一次性抑制、Edit/Think/undefined 的阶段重置、retry 回滚、禁用 allowance、歧义注册、以及桥接 MCP kind;Session 测试断言只有一条提醒到达 provider、第三次读取仍然执行、且提醒是后续消息里的最后一个 part。移除该功能会让两者都失败。

(时序图见上,中文不重复:流程是 ToolCallRequest 逐事件 record,Finished 时 commit、Retry 时 rollback,工具结果轮次上按 allowance 调 takeReminder 拿到一次性提醒并随工具结果一起发给模型,四个逻辑轮次边界处 reset;图中也标出了 ModelFallback 不回滚这一点。)

测试

本次是无人值守的 CI 重跑,按闸门规则我没有执行 PR 里的任何东西 —— 没有构建、没有跑测试、没有 gh pr checkout。下面的证据是 PR 自己的 CI,通过 API 读取所审查 commit 的结果。真实场景 tmux 测试在本路径下为 N/A;maintainer 可以触发(见下方通道说明)。

2525fee6 上全部 34 个 check-run 均已结束:0 失败、0 pending,三个 pull_request workflow run(Qwen Code CI、SDK Java、tui-parity)都成功完成。没有红灯,所以没有失败 job 的日志片段可引。被跳过的 job —— Test (macos-latest)、Test (windows-latest)、Integration Tests (CLI, No Sandbox) 以及五个编排 job —— 是 workflow 自身过滤条件导致的 skipped,不是失败。diff 是与平台无关的 TypeScript,没有路径、文件系统、进程或 shell 面,所以 ubuntu 单测全绿加 lint 加 no-AK 集成运行对它是足够的覆盖;Java SDK 矩阵与本 diff 无关,也同样是绿的。

(CI 表格见上方机器可读区域,中文不重复:34 个 check,0 失败 0 pending,Java SDK 矩阵合并为一行。)

沙箱验证能补上 CI 补不了的部分:@qwen-code /verify —— 在当前 head 上,提醒是否真的出现在发往 provider 的请求里、之后一次合理的读取是否仍能执行、以及 provider 重试是否无法把提醒投递两次。单测和 Session 测试是基于 mock 固定这些机制的,而作者自己的原生报告是针对受控 loopback provider 自行运行的,因此目前还不存在针对 base 构建的独立 A/B。@qwen-code /tmux 是交互面的通道,因为提醒是发给模型的文本,用户不会直接看到,但它会改变模型接下来的行为。作者有写权限,两个通道都可以直接使用。

未验证的部分及原因:生产模型的收敛效果与 token 节省 —— 完全没有证据,且 PR 明确将其列为范围之外,所以我把它当作一条未经证明但成本很低的提示,而不是已被证实的收益。同样未验证:Windows 与 Linux 的运行时行为,作者自己的表格也标注未测(diff 没有平台相关面,所以我不认为这是值得阻断的缺口)。作者在本线程中给出的 tmux capture、请求历史与源码哈希身份是作者的主张,不是我重跑得到的证据 —— 我无法重跑,也没有拿它们替代证据。

— Qwen Code · qwen3.8-max-2026-09-02

Reviewed at 2525fee66359cd06211e48f7ee06982c2b5043d2 · re-run with @qwen-code /triage

@doudouOUC

Copy link
Copy Markdown
Collaborator

独立复核确认:本 PR 实现的"只读探索收敛提醒"与 #13321 的诉求一致,设计与代码改动自洽。下面给出按 PR head bb78e71f 独立走查源码得到的证据,便于 reviewer 直接核对。

提醒阈值与 disable/Infinity 语义对齐

ToolExplorationBudget.takeReminder(allowance)(packages/core/src/services/tool-exploration-budget.ts:33-44)在 !Number.isFinite(allowance) || allowance <= 0 || this.calls < allowance || this.reminded 时返回 undefined,命中时设置 reminded=true 并返回 TOOL_EXPLORATION_REMINDER(一次性)。这与 loopDetectionService.ts 里 getMaxToolCallsPerTurn() 的契约一致——loopDetectionService.ts:1596-1604 注释明确:"Per-turn cap. getMaxToolCallsPerTurn() is the configured value (already resolved, Infinity when disabled)"。因此:

  • 显式配置 → allowance 为有限值,到达阈值即提醒一次;
  • 未配置(默认自适应)→ getMaxToolCallsPerTurn() 返回软阈值,提醒在软阈值处插入,硬回退仍由 checkTurnToolCallCap 负责(loopDetectionService.ts:1610-1618 调 shouldHaltOnTurnToolCallCap(... isMaxToolCallsPerTurnExplicit()),与提醒互不干扰);
  • 禁用/无限 → !Number.isFinite 直接 short-circuit,不提醒,符合 PR "禁用或无限 allowance 不产生提醒"。

core 路径:record / commit / rollback 与 loop guard 同源

client.ts:4967-4984 把 budget 的事件接入与 loopGuardFedCallIds 去重绑定到同一个 duplicateLoopGuardRequest 判定:

if (event.type === ToolCallRequest && !duplicateLoopGuardRequest) {
  budget.record(getToolExplorationKind(registry, event.value.name, event.value.args));
} else if (event.type === Finished) {
  budget.commit();
} else if (event.type === Retry) {
  budget.rollback();
}

这与 loopDetectionService.ts 的 Retry 处理对齐——checkAlwaysOnSafeties 的 Retry 分支(loopDetectionService.ts:660-697)注释明确 retry 会 replay 失败 attempt 的 tool calls,并 clear 重复计数器;budget 的 rollback()(tool-exploration-budget.ts:50-54)把 calls/reminded 回滚到 committedCalls/committedReminded,语义一致——一次 retry 不会把已撤销的 read 计入探索阶段,也不会重复投递已发过的提醒。provider 重复 callId 的去重由 duplicateLoopGuardRequest(client.ts:4955-4962,基于 loopGuardFedCallIds.has(fedCallId))保证,budget 复用同一判定,与 #9450 的 dedup 同源。

提醒插入点 client.ts:4797-4805 用 this.loopDetector.isDisabledForSession() 作前置闸——isDisabledForSession() 是本 PR 在 loopDetectionService.ts:455-457 新增的访问器,返回 this.disabledForSession(在 :448 由交互式 disable 设置)。这样"会话级 loop-detector disable 也抑制 core 提醒"成立,且与 checkAlwaysOnSafeties:788 的 if (this.disabledForSession) ... 共用同一开关,行为统一。

reset 覆盖面

budget 的 reset() 在 user turn / Goal / Stop-hook 进入处调用:client.ts:3805(startsInteraction)、:4146(Goal)、:5312(Stop-hook goal)、:5392(Stop-hook continuation)。这覆盖了 loopDetector.reset(prompt_id) 的所有既有 reset 点(PR 在每个 this.loopDetector.reset(prompt_id) 旁边都加了 this.toolExplorationBudget.reset()),逻辑轮次边界与既有 loop-detector 完全对齐,不会出现 budget 跨轮次泄漏。

kind 分类与桥接 MCP 工具

getToolExplorationKind(tool-exploration-budget.ts:25-42)通过 canonicalToolName → resolveRegisteredToolName(canonical, registry.getAllToolNames()) 解析目标:当 name === ToolNames.TOOL_CALL 且 args.name 为 string 时改用桥接目标名,否则用传入名。resolveRegisteredToolName(tool-names.ts:233-244)的歧义返回是 string[](多个 case-insensitive 命中),budget 在 :35 用 Array.isArray(resolved) → undefined 处理——即歧义名(如同时注册 READ_FILE/Read_File)按"未分类"处理,结束当前 read 阶段,这是保守且安全的方向。tool-exploration-budget.test.ts:43-49 与 :51-68 分别覆盖了歧义未分类与桥接 MCP 工具两种情形。

一个非阻塞观察

record()(tool-exploration-budget.ts:30-38)对非 Read/Search/Fetch kind 直接 calls=0; reminded=false——即一个失败的 Edit/Think 调用也会重置探索阶段。PR 设计文档(docs/design/tool-exploration-convergence.md:18-20)已显式声明这是有意为之:"A non-read request resets the phase even if its execution later fails; the existing failure protections retain responsibility for that case." 这与 #10887 的重复失败保护职责切分清晰,不构成本 PR 的问题,仅提示 reviewer 确认该切分符合预期——如果未来希望"探索阶段被失败的非读调用打断后、下一轮只读继续累积",需要单独再提,当前实现按设计文档是有意为之。

测试

tool-exploration-budget.test.ts(88 行)覆盖:阈值一次性 + 合法继续(:8-16)、实现/规划/未知 kind 重置(:18-29)、retry 回滚不重复提醒(:31-41)、disabled/Infinity/0(:43-47)、歧义未分类与桥接 MCP(:49-68)。Session.test.ts:20548-20590 在 ACP 路径上验证"read 结果后插入一次提醒、允许继续 read、提醒文本含 does not authorize writes",并断言 execute 被调用 3 次(2 次触发阈值 + 1 次合法继续)。core 与 ACP 两条路径均有落点。

结论:设计与实现一致、与既有 loop-detector / cap 语义对齐、测试到位,建议合入。

@qwen-code-review-bot

qwen-code-review-bot commented Oct 7, 2026 •

Copy link
Copy Markdown
Collaborator

Confidence: 4/5 — the code is sound and I verified the wiring end to end; the one nit is a single missing event type, and my only real reservation is a product judgment that is not mine to make and is already parked with the assigned maintainer.

To be explicit about what this score is not: the fork-refactor guardrail did not fire (GUARD = ok — this is a feat), and Stage 0 raised no size escalation (140 production lines against a 500-line threshold). So 4/5 is my honest read of the code, not a policy cap, and the missing point is the ModelFallback finding plus the unproven-effectiveness question below.

Going back to my independent proposal: I would have reached for the same thing, and for the same reason the PR did. My first idea — host the counter in LoopDetectionService and inherit its existing hooks — fails on the daemon, which cannot use that class. The repo already solved that problem once, by extracting a small pure helper into core and importing it from both runtimes (shouldHaltOnTurnToolCallCap), and this PR repeats the move rather than inventing a parallel mechanism. That is the part I weigh most heavily: it is not a new abstraction, it is the existing one applied a second time.

On whether the problem exists — I did not accept the framing. The historical session in #13321 was never reproduced on main and its version was never recorded, so the user-level harm rests on one unreproduced incident. But the mechanism gap is checkable and I checked it: getMaxToolCallsPerTurn() resolves a non-positive config to Infinity, and the adaptive default only halts a diverse-call turn on a stuck-repetition signal or at the hard backstop, so 100 distinct successful reads pass the soft allowance with nothing asking the model to consolidate. That is a real hole in a policy this repo has already decided to ship, and closing it with an advisory sentence rather than a new halt is the proportionate response.

What I would flag for the maintainer, none of it blocking:

  • The ModelFallback rollback gap from the review comment. One-line fix; the core path currently contradicts an invariant its own adjacent code states.
  • The reminder has no dedicated setting. It is suppressed only by a disabled/infinite model.maxToolCallsPerTurn on both paths, and additionally by the interactive loop-detector disable on the core path — which has no ACP equivalent, so daemon sessions have one less route to turn it off. For an advisory feature whose payoff is unmeasured, inheriting the cap's configuration is defensible and keeps the diff minimal, but it does mean this ships always-on for every session that crosses the allowance. Worth a deliberate yes rather than a default.
  • Volume, stated plainly because the gate is supposed to notice it: 18 open PRs from this author, 11 opened today. That is a reason to read each one on its own merits with more skepticism, not less, and it is why I verified the integration against main instead of skimming. It is not a defect in this PR, and I did not let it argue either direction here.

Would I curse whoever wrote this in six months? No. It is 140 additive lines with zero deletions, no drive-by refactor, tests that fail if you remove the feature, and design docs in both languages with reciprocal links. The class has four methods and no state machine cleverness, and the reset wiring is complete at all four logical-turn boundaries — which is the thing that usually rots in this area and the thing I spent most of my time on.

So: approving on the code. I am not signing off on the product direction, and I want that to be unambiguous — #13321 is still open and carries need-discussion, the previous pass escalated exactly this question, and it is assigned to @DragonnZhang with five reviewers requested. Whether an unproven advisory nudge is worth its tokens on every long read-only turn is a call for a maintainer, and main requiring two approving reviews means that call is still theirs to make. My approval is the code-review vote: the implementation is correct, minimal, tested, and idiomatic, and CI is green on the reviewed commit.

中文说明

信心:4/5 —— 代码是可靠的,接线我从头到尾核实过;唯一的瑕疵是少了一个事件类型,而我真正的保留意见是一个不该由我做的产品判断,并且已经停在被指派的 maintainer 那里。

明确说明这个分数不是什么:fork refactor 护栏没有触发(GUARD = ok —— 这是 feat),Stage 0 也没有按规模上报(140 行生产代码,阈值是 500)。所以 4/5 是我对代码的真实判断,不是策略性封顶;扣掉的一分是 ModelFallback 那条发现,加上下面的效果未证实问题。

回到我最初的独立方案:我会做出同样的东西,而且理由和 PR 一致。我最早的想法 —— 把计数器放进 LoopDetectionService 复用现成钩子 —— 在 daemon 上走不通,因为 daemon 用不了那个类。本仓库已经把这个问题解过一次:把一个小的纯判定函数抽到 core,由两个运行时共同引入(shouldHaltOnTurnToolCallCap)。这个 PR 是重复这个既有动作,而不是另造一套机制。这一点是我最看重的:它不是新的抽象,而是同一个抽象被第二次正确使用。

关于问题是否存在 —— 我没有照单接受 PR 的叙述。#13321 里那次历史会话从未在 main 上复现,版本也没有留档,所以用户层面的损害只建立在一次未复现的事件上。但机制缺口是可核查的,我核查了:getMaxToolCallsPerTurn() 会把非正数的配置解析为 Infinity,而自适应默认只在出现重复卡死信号或触到硬兜底时才停,所以 100 次参数各异的成功读取可以越过软阈值,没有任何东西要求模型收敛。这是本仓库已经决定要做的策略里的一个真实缺口,用一条建议性语句而不是新的停止条件去补,是与问题相称的回应。

以下是我会提给 maintainer 的点,都不构成阻断:

  • 审查评论里的 ModelFallback 回滚缺口。一行修复;core 路径目前与它自己相邻代码所声明的不变量相矛盾。
  • 这条提醒没有专门的配置项。两条路径上它只会被禁用/无限的 model.maxToolCallsPerTurn 抑制,core 路径还额外受交互式 loop-detector 会话禁用影响 —— 而后者在 ACP 没有对应物,所以 daemon 会话少了一条关闭途径。对一个收益未经测量的建议性功能来说,复用上限的配置是说得通的,也让 diff 保持最小,但这确实意味着它对所有越过 allowance 的会话都是默认开启的。这值得一次明确的"同意",而不是靠默认通过。
  • 数量,直说,因为闸门本来就该注意到:这位作者有 18 个 open PR,其中 11 个是今天开的。这应该让我以更多而非更少的怀疑去逐一看每个 PR 的实质,这也是我选择对照 main 核实接线、而不是扫一眼就过的原因。它不是这个 PR 的缺陷,我也没有让它在这里偏向任何一个结论。

六个月后我会骂写这段代码的人吗?不会。140 行纯新增、零删除、没有顺手重构、移除功能测试就会失败、两种语言的设计文档带互相指向的链接。那个类只有四个方法,没有状态机式的花招,而 reset 接线在全部四个逻辑轮次边界上都完整 —— 这恰恰是这个区域最容易腐坏的地方,也是花时间最多的地方。

所以:就代码而言我批准。我没有为产品方向背书,这一点我要说清楚 —— #13321 仍然 open 并带 need-discussion,上一轮上报的正是这个问题,现在指派给 @DragonnZhang,并已请求五位 reviewer。在每一轮长只读对话里,一条效果未经证明的建议性提醒值不值得它占用的 token,这是 maintainer 的判断;而 main 需要两个 approving review,意味着这个判断仍然在他们手上。我的批准是代码审查这一票:实现正确、最小、有测试、符合本仓库惯例,且所审查 commit 上 CI 全绿。

— Qwen Code · qwen3.8-max-2026-09-02

Reviewed at 2525fee66359cd06211e48f7ee06982c2b5043d2 · re-run with @qwen-code /triage

recordDaemonToolCalls fed the exploration budget at the top of its
per-call loop, before the per-turn cap and global-duplicate checks. A
batch that those checks halt is skipped whole and never executes, yet
its calls still counted toward the budget and still resolved every tool
name through the registry. Move the recording after both halt checks so
only calls the turn actually runs feed the budget, and a capped turn
performs no registry lookups.

Also complete the client-goal Config double with getMaxToolCallsPerTurn
and getToolRegistry, which the new budget call sites require.

Co-authored-by: Qwen-Coder <[email protected]>
Patrol-Run: qwen-pr-conflict/jmuy5teh2cj
@yiliang114

Copy link
Copy Markdown
Collaborator Author

Added scope/core for maintainer routing. The latest triage raised a product acceptance gate rather than a verified code defect: this PR deliberately adds a bounded read/search/fetch convergence reminder, while full domain-level convergence and measured token savings remain outside the evidence collected so far. The current-head local and actual CLI/daemon-ACP tmux report distinguishes controlled-provider behavior from real-model effectiveness.

I am retaining Addresses #13321, keeping the issue open, and leaving the product-direction decision with the assigned maintainer. No speculative policy expansion or unrelated refactor has been added.

中文:已补 scope/core 标签供 maintainer 评估。当前改动与本地、真实 CLI/daemon-ACP tmux 报告证明的是有界的收敛提醒行为,还没有证明原生产场景的语义收敛或实际 token 降幅。继续按 Addresses #13321 跟进,issue 保持开放,产品方向需要 maintainer 判断。

@yiliang114

Copy link
Copy Markdown
Collaborator Author

Current-head follow-up at 2525fee66359cd06211e48f7ee06982c2b5043d2.

The new additive commit moves exploration-budget recording past the existing cap and duplicate halt checks and completes the client-goal Config mock. This verification keeps the current daemon path attributable to its changed runtime bytes.

Local checks: 56 client-goal tests passed with zero skips; two selected Session cap/duplicate cases passed (1,153 other cases intentionally skipped). The selected cases verify the existing halt behavior, not the internal exploration counter of a discarded batch. Fresh CLI build/typecheck passed. The core production tree is unchanged by this follow-up, so the earlier core headless run is retained at its original recorded identity rather than rerun or relabeled.

PR #13601 current-head daemon/ACP verification

PASS at 2525fee66359cd06211e48f7ee06982c2b5043d2. One ordinary daemon/ACP scenario ran through the real native CLI, workspace-runtime admission, session prompt admission and SSE stream. Responses came from an anonymous controlled loopback provider; this is runtime-mechanics evidence, not production-model convergence or token-savings evidence.

The isolated profile left model.maxToolCallsPerTurn unset, using the default adaptive allowance of 100 rather than an explicit hard cap. The provider requested 101 distinct native read_file calls, then one additional read, then natural completion. All 102 actual file results matched the anonymous input bytes exactly (1,938 bytes total). ACP emitted 102 completed tool updates; local telemetry independently recorded 102 unique successful read_file calls.

Main request Exact native tool results Reminder position Last tool-result position
1 0 absent —
2 101 104 103
3 102 104, same single reminder 106

Positions are zero-based wire-message indices. The reminder first appeared after the 101 results. The continuation still advertised read_file; the 102nd call executed. No second reminder was appended, no accidental hard-cap terminal occurred, and the admitted prompt ended with exactly one turn_complete/end_turn. Final state was idle, with no active prompt or turn error. The main-request count excludes one managed-memory request and one suggestion request, identified from their actual system/purpose text. Their replayed history carries the same existing reminder.

Source bytes matched the current committed files. Pre/post source and compiled-module hashes were unchanged. A read-only Node load hook delegated to the normal loader and recorded the actual CLI and ACP-child loads, including the current Session module and core budget module. Generated commit metadata still reports 464f486e2019; it predates this candidate and was not used as loaded-byte identity.

Candidate source or compiled module SHA-256, unchanged before/after
packages/core/src/services/tool-exploration-budget.ts ffa33a66937225f9d821b332eaeaaa8705e03686e1a7a6afac81fee88b413070
packages/core/src/core/client.ts 8a65505dca0e5d5e370385e6cc4d05e0e8fe3f5de3d70c21dcc6df85ae2d46a0
packages/cli/src/acp-integration/session/Session.ts afbb46466ddf82894882b202748b8e396e33be8a2723b90ccf4685d1a7d692fa
packages/cli/src/cli.ts f8563c416eb7a61aaf55e5a11e9a58d856af9c40e45c1cc391bc78719fe1fb6c
packages/core/dist/src/services/tool-exploration-budget.js 0b41f7d892122d3de411cfda400956d482d4d9cdfb00c3361fcc1f85b9dfa2b9
packages/core/dist/src/core/client.js f713fcd604a3607d5ae740bf33fe28b674699c35c8c0d0eb83482ed827d2915b
packages/cli/dist/src/acp-integration/session/Session.js cfeaa9deba7a2bcf99a78e06830f7fa10162678be3a071c1c17d80b8d8ee0b49
packages/cli/dist/index.js 43c7251b6e923a9d112f6a5dd694725fcc1bcdfafd9225ad1c05dbc13981eabf
packages/cli/dist/src/cli.js 8709cd476aaa73ba0f048f7822aff563b48c55df725c3aeaf2ffd2095abc26bb

Actual owned tmux capture excerpt (identifiers, local paths and process IDs sanitized; original capture retained):

ACTUAL_DAEMON_READY pid=<owned-process> defaultAllowanceSetting=UNSET
ACTUAL_PROMPT_ADMITTED {"promptId": "<id>", "lastEventId": 0, "eventEpoch": "<id>"}
ACTUAL_TERMINAL {"id": 316, "v": 1, "type": "turn_complete", "promptId": "<id>", "data": {"sessionId": "<id>", "stopReason": "end_turn", "promptId": "<id>", "branchPoint": {"assistantRecordUuid": "<id>", "checkpointUuid": "<id>"}}, "originatorClientId": "client_<id>", "_meta": {"serverTimestamp": 1791384990008}}
ACTUAL_NATIVE_DONE events=316 state={"sessionId": "<id>", "workspaceCwd": "<owned-fixture>/daemon/workspace", "createdAt": "2026-10-07T14:56:28.417Z", "updatedAt": "2026-10-07T14:56:30.008Z", "clientCount": 1, "hasActivePrompt": false, "activeWorkState": "idle", "hasRunningBackgroundTasks": false, "isWaitingForPermission": false, "isWaitingForUserQuestion": false, "pendingInteractionCount": 0, "hasTurnError": false, "pendingInteractions": []}
OWNED_DAEMON_STOPPED

Only this changed daemon path was run. Core headless behavior, real-model semantics, duplicate/cap negative controls, reset, retry and permission controls were not additional native scenarios. No product source, dependencies, Git/GitHub state or global services were changed. Raw requests/responses, HTTP receipts, SSE events, module loads, telemetry, file manifest and original tmux capture are retained. The result and identity receipts record the assertions above.

Cleanup verified: both owned tmux sessions and processes stopped, both owned listeners closed, and the owned profile/runtime/workspace directories removed. Raw evidence remains.

中文说明

当前提交 2525fee 的普通 daemon/ACP 路径通过一次真实原生运行验证。独立配置没有显式设置 100 次硬上限,实际使用默认自适应 allowance。前 101 次真实文件读取完成后,第二次主模型请求在最后一个工具结果之后插入一条探索提醒;第 102 次读取仍正常执行,第三次主请求包含全部 102 个精确结果,只保留已有提醒,没有追加第二条。实际文件内容合计 1,938 字节,ACP 的 102 个完成事件和本地 telemetry 的 102 个唯一成功调用共同佐证读取行为。

该提示没有造成新的终止:同一获准 prompt 收到唯一的 turn_complete/end_turn,会话进入 idle,未发生 turn error。主请求共三次;另有各一次 managed-memory 和 suggestion 请求,按实际请求内容归因并从主请求统计中排除。辅助请求中的历史提醒不计为新的插入。

加载记录证明真实 ACP 子进程使用当前编译后的 Session 和 core budget 模块;运行前后源代码与编译产物哈希一致。生成的版本元信息仍显示较早的 464f486e2019,本报告明确区分它与实际加载字节的身份。本次 provider 是匿名本地受控服务,因此只证明运行时计数、注入、继续调用和自然结束,不证明生产模型的语义收敛或 token 节省。没有重跑 core headless,也没有扩大成负向控制矩阵;原始证据保留,清理仅涉及本次拥有的进程、tmux、配置和运行目录。

清理已核实完成:本次 provider 与 daemon 进程、两个 tmux 会话和监听端口均已关闭,只删除本次独立配置、运行目录及匿名输入文件;原始请求、事件、tmux 和哈希证据保留。

中文补充:当前 2525fee 增量提交后,本地 56 个 client-goal 测试及两个定向 cap/重复调用 Session 用例通过;其余 1,153 个 Session 用例未执行,不计入通过数。fresh CLI build/typecheck 通过。此次额外原生验收仅覆盖变更后的 daemon/ACP 路径;core 生产逻辑没有变化,先前 headless 报告继续保留原提交身份。仍按 Addresses #13321 跟进,产品方向、生产模型收敛及 token 节省尚未证明;PR 未合并,issue 保持开放。

@qwen-code-review-bot

Copy link
Copy Markdown
Collaborator

Qwen Code review did not complete successfully. The review pipeline failed before a review could be posted. A transient error is retried automatically; if you are seeing this, retry with @qwen-code /review. See workflow logs.

@yiliang114

Copy link
Copy Markdown
Collaborator Author

The corrected productive-phase control passed at 2525fee66359cd06211e48f7ee06982c2b5043d2: one corrective native CLI/tmux attempt, retry 0, exit 0, natural completion. It executed 102 real tools: 99 distinct read_file calls → one separate edit creation → two verification reads. All 102 terminal receipts succeeded; next-request history independently contained 102 tool results. The provider received the 99 read results before issuing the edit, then the actual Created new file: … with provided content. result before issuing verification reads.

The summary was derived from actual read payloads and matched the independent expected bytes exactly: 1,377 bytes, SHA-256 8b645af48accd1e63de05dac3242d023fd79fe02e35ff809baf4cadbbc7f23f6. Traffic was 4 primary requests, 0 memory, 0 suggestion, with prior-result counts 0/99/100/102. No exploration reminder appeared in any model-bound request. The adaptive allowance remained unset (default 100); the actual edit is registered as Kind.Edit, whose matched budget implementation resets the continuous read-only phase.

All 26 scoped source/runtime identities and HEAD stayed fixed; fixture helpers stayed fixed. Eleven actually loaded modules matched the manifest. The edit source hash was e2d196b45adb96ab14a14fb1b0583a6a5694e9a39a73949d69964b9d587af71c; loaded edit runtime was 09a0c0e43dbae3d8f94c888762ceb069169ac6a2beacc89e1258414d66fcbcfd, with current source emission matching. Loaded budget was 0b41f7d892122d3de411cfda400956d482d4d9cdfb00c3361fcc1f85b9dfa2b9; client was f713fcd604a3607d5ae740bf33fe28b674699c35c8c0d0eb83482ed827d2915b. No build or unit rerun was needed.

The actual tmux excerpt and compact result receipt are included below. There were two native attempts overall: a first fixture-selection failure with 0 tools, followed by this one corrected control. Neither used automatic retries. The first attempt remains recorded and is not acceptance evidence. The controlled localhost provider verifies phase mechanics and productive non-interference, not production-model semantic convergence or complete #13321 acceptance. Owned provider/tmux/config/runtime were cleaned up; fixture helpers and test files remain for review.

Actual tmux capture excerpt: edit result, verification reads, natural completion

Paths and identifiers are redacted. This is an excerpt of the actual captured terminal, with terminal wrapping retained. Usage values are mock-provider fixture values, not real-model token measurements. The write success is present before the two verification calls.

{"type":"user","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"message":{"role":"user","content":[{"typ
e":"tool_result","tool_use_id":"call_<ID>","is_error":false,"content":"Created new file: <ARTIFACT_DIR>/workspace/sum
mary.txt with provided content. Showing lines 1-100 of 100 from the edited file:\n\n---\n\nrecord-001=1\nrecord-002=2\nrecord-003=3\nrecord-004=4\nrecord-005=5\nrecord-006=6\nrecor
d-007=7\nrecord-008=8\nrecord-009=9\nrecord-010=10\nrecord-011=11\nrecord-012=12\nrecord-013=13\nrecord-014=14\nrecord-015=15\nrecord-016=16\nrecord-017=17\nrecord-018=18\nrecord-0
19=19\nrecord-020=20\nrecord-021=21\nrecord-022=22\nrecord-023=23\nrecord-024=24\nrecord-025=25\nrecord-026=26\nrecord-027=27\nrecord-028=28\nrecord-029=29\nrecord-030=30\nrecord-0
31=31\nrecord-032=32\nrecord-033=33\nrecord-034=34\nrecord-035=35\nrecord-036=36\nrecord-037=37\nrecord-038=38\nrecord-039=39\nrecord-040=40\nrecord-041=41\nrecord-042=42\nrecord-0
43=43\nrecord-044=44\nrecord-045=45\nrecord-046=46\nrecord-047=47\nrecord-048=48\nrecord-049=49\nrecord-050=50\nrecord-051=51\nrecord-052=52\nrecord-053=53\nrecord-054=54\nrecord-0
55=55\nrecord-056=56\nrecord-057=57\nrecord-058=58\nrecord-059=59\nrecord-060=60\nrecord-061=61\nrecord-062=62\nrecord-063=63\nrecord-064=64\nrecord-065=65\nrecord-066=66\nrecord-0
67=67\nrecord-068=68\nrecord-069=69\nrecord-070=70\nrecord-071=71\nrecord-072=72\nrecord-073=73\nrecord-074=74\nrecord-075=75\nrecord-076=76\nrecord-077=77\nrecord-078=78\nrecord-0
79=79\nrecord-080=80\nrecord-081=81\nrecord-082=82\nrecord-083=83\nrecord-084=84\nrecord-085=85\nrecord-086=86\nrecord-087=87\nrecord-088=88\nrecord-089=89\nrecord-090=90\nrecord-0
91=91\nrecord-092=92\nrecord-093=93\nrecord-094=94\nrecord-095=95\nrecord-096=96\nrecord-097=97\nrecord-098=98\nrecord-099=99\n"}]}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"message_start","
message":{"id":"<ID>","role":"assistant","model":"productive-controlled","content":[]}}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"content_block_st
art","index":0,"content_block":{"type":"tool_use","id":"call_<ID>","name":"read_file","input":{}}}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"content_block_de
lta","index":0,"delta":{"type":"input_json_delta","partial_json":"{\"file_path\":\"<ARTIFACT_DIR>/workspace/summary.txt\",\"offse
t\":0,\"limit\":99}"}}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"content_block_st
op","index":0}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"content_block_st
art","index":1,"content_block":{"type":"tool_use","id":"call_<ID>","name":"read_file","input":{}}}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"content_block_de
lta","index":1,"delta":{"type":"input_json_delta","partial_json":"{\"file_path\":\"<ARTIFACT_DIR>/workspace/input-099.txt\",\"off
set\":0,\"limit\":1}"}}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"content_block_st
op","index":1}}
{"type":"assistant","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"message":{"id":"<ID>","type":"message","role":"assistant","model":"productive-controlled","content":[{"type":"tool_use","id":"call_<ID>","name":"read_file","input":{"file_
path":"<ARTIFACT_DIR>/workspace/summary.txt","offset":0,"limit":99}},{"type":"tool_use","id":"call_<ID>","name":"read
_file","input":{"file_path":"<ARTIFACT_DIR>/workspace/input-099.txt","offset":0,"limit":1}}],"stop_reason":"tool_use","usage":{"i
nput_tokens":12616,"output_tokens":63,"cache_read_input_tokens":0,"total_tokens":12679}}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"message_stop"}}
{"type":"user","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"message":{"role":"user","content":[{"typ
e":"tool_result","tool_use_id":"call_<ID>","is_error":false,"content":"Read lines 1-99 of 100 from ../../../../..<ARTIFACT_DIR>/workspace/summary.txt"}]}}
{"type":"user","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"message":{"role":"user","content":[{"typ
e":"tool_result","tool_use_id":"call_<ID>","is_error":false,"content":"Read lines 1-1 of 2 from ../../../../..<ARTIFACT_DIR>/workspace/input-099.txt"}]}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"message_start","
message":{"id":"<ID>","role":"assistant","model":"productive-controlled","content":[]}}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"content_block_st
art","index":0,"content_block":{"type":"text","text":""}}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"content_block_de
lta","index":0,"delta":{"type":"text_delta","text":"Productive control complete: 99 reads, one summary creation, and two verification reads succeeded."}}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"content_block_st
op","index":0}}
{"type":"assistant","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"message":{"id":"<ID>","type":"message","role":"assistant","model":"productive-controlled","content":[{"type":"text","text":"Productive control complete: 99 reads, one summary creation
, and two verification reads succeeded."}],"stop_reason":null,"usage":{"input_tokens":13186,"output_tokens":25,"cache_read_input_tokens":0,"total_tokens":13211}}}
{"type":"stream_event","uuid":"<ID>","session_id":"<ID>","parent_tool_use_id":null,"event":{"type":"message_stop"}}
{"type":"result","subtype":"success","uuid":"<ID>","session_id":"<ID>","is_error":false,"duration_ms":467,"duration_
api_ms":312,"num_turns":4,"result":"Productive control complete: 99 reads, one summary creation, and two verification reads succeeded.","usage":{"input_tokens":41467,"output_tokens
":3090,"cache_read_input_tokens":0,"total_tokens":44557},"permission_denials":[]}

Native exit: 0; provider receipts captured.
Compact result receipt
{
  "head": "2525fee66359cd06211e48f7ee06982c2b5043d2",
  "verdict": "passed_controlled_productive_phase",
  "cliExit": 0,
  "naturalCompletion": true,
  "execution": {
    "totalToolCalls": 102,
    "readFileCalls": 101,
    "initialDistinctReads": 99,
    "editCreations": 1,
    "verificationReads": 2,
    "nativeToolResults": 102,
    "nativeErrorResults": 0,
    "nextRequestToolResults": 102,
    "sequence": [
      [
        "read_file",
        99
      ],
      [
        "edit",
        1
      ],
      [
        "read_file",
        2
      ]
    ],
    "writeAndVerificationSeparated": true,
    "editResultSuccessGatePassed": true
  },
  "summary": {
    "bytes": 1377,
    "sha256": "8b645af48accd1e63de05dac3242d023fd79fe02e35ff809baf4cadbbc7f23f6",
    "expectedSha256": "8b645af48accd1e63de05dac3242d023fd79fe02e35ff809baf4cadbbc7f23f6",
    "exactBytesMatch": true,
    "derivedFromActual99ReadResults": true
  },
  "requests": {
    "primary": 4,
    "memory": 0,
    "suggestion": 0,
    "other": 0,
    "primaryPriorResultCounts": [
      0,
      99,
      100,
      102
    ],
    "explorationReminders": 0
  },
  "allowance": {
    "configured": false,
    "resolvedDefault": 100,
    "evidence": "Matched unchanged config and loaded loop detector default; total102 completes beyond default100 without hard-cap override"
  },
  "identity": {
    "entries": 26,
    "beforeAfterStable": true,
    "loadedMatchManifest": true,
    "editKind": "Kind.Edit",
    "editSourceSha256": "e2d196b45adb96ab14a14fb1b0583a6a5694e9a39a73949d69964b9d587af71c",
    "editRuntimeSha256": "09a0c0e43dbae3d8f94c888762ceb069169ac6a2beacc89e1258414d66fcbcfd",
    "editEmissionMatches": true
  }
}

中文:纠正后的控制在同一 2525fee head 通过。仅运行一次,retry 0、exit 0,自然完成 102 个真实工具:99 个不同文件读取 → 独立 edit 创建汇总 → 收到真实创建成功结果后再做两次验证读取。102 个终端结果均成功,下一请求历史也有 102 个工具结果;4 个主请求、memory 0、suggestion 0,均未出现 exploration reminder。汇总由真实读取结果生成,1,377 字节与独立预期完全一致。默认 allowance 未设置,edit 的 Kind.Edit 与实际加载预算实现对应重置只读阶段。26 项源码/产物身份前后固定,11 个真实加载模块哈希匹配;未重复构建或单测。先前 0 工具的 fixture 设置失败证据保留。此次受控 provider 只证明阶段机制及实际写入后的验证流程不受探索提醒影响,不代表真实模型语义收敛或 #13321 完整验收。下方保留实际脱敏 tmux 片段和结果回执;完整 capture、schema、fixture 与输入/输出也已在本地保留,自有进程、tmux、运行配置已清理。整体是一次 0 工具的设置失败和一次纠正运行,两次均没有自动重试。capture 中的 usage 数字来自模拟 provider,不能作为真实模型 token 或节省量。

@yiliang114

Copy link
Copy Markdown
Collaborator Author

@qwen-code /triage

@qwen-code-review-bot

qwen-code-review-bot commented Oct 7, 2026 •

Copy link
Copy Markdown
Collaborator

Sandboxed verification: ❌ not passed — findings reported (agent verdict) - workflow run

Ran the PR in an isolated, token-free container: A/B against the base build, mock-free harness assertions, targeted gates. Advisory evidence for human reviewers — not a review, an approval, or a CI check.

Scripted assertions: 1925 passed · 0 failed · 1925 total

Flakiness gate: ⚠️ timeout — only 3 of 5 rounds fit the 15-minute budget; the completed rounds agreed

中文 — 判定:❌ 不通过 · 报告了发现(agent 判定)

沙箱验证在隔离、无凭证的容器中执行了该 PR 的代码(与 base 构建 A/B 对照、无 mock harness 断言、定向门禁)。仅作为评审证据,不构成评审、批准或 CI 检查。

脚本断言:1925 通过 · 0 失败 · 1925 总计

抖动门:⚠️ timeout — only 3 of 5 rounds fit the 15-minute budget; the completed rounds agreed

Verification report

PR #13601 deep verification — feat(core): add a convergence reminder for read-only exploration

Verdict: findings — the central claim is proven load-bearing end-to-end on the provider wire (head 1 delivery / base 0, across 4 scenario pairs, 8/8 cells green). No defect was demonstrated and nothing here is blocking. The findings are two evidenced completeness gaps: the entire core-side wiring is unasserted (5/5 mutations survived a 554-test suite that provably executes the path), and commit 2525fee6's behavioural claim is not asserted by any test.

  • Verified head: 2525fee66359cd06211e48f7ee06982c2b5043d2 (git rev-parse HEAD^2)
  • A/B control: 718ae1e6c6da2878f4ec3c502e9915b89c9545e2 (HEAD^1, the merge-ref base tip)
  • Assertions executed: 1925 pass / 0 fail (61 harness + 1864 unit-gate; composition below)
中文摘要

结论:findings(有问题值得关注,但不阻塞合并)。

  • A/B 结论:中心主张成立且可证明为"承重"。用真实构建产物(dist/cli.js)配合本地回环 OpenAI 兼容 provider,对 head 与 base 各跑 4 个场景:显式上限 3、默认自适应上限 100(102 次真实 read_file)、上限被禁用(0 → Infinity)、以及中途插入 Execute 类工具触发阶段重置。head 侧每个场景恰好投递 1 次提醒并落在预期的那一次续跑请求上;base 侧 0 次,其余可观察量(请求数、工具响应数、退出码)完全一致。8/8 单元全部通过。另加一个故障注入单元:在携带提醒的那次请求上返回 500,CLI 自行重试后仍是 恰好 1 次投递,既不重复也不丢失。证据见 01-ab-matrix-head-vs-base.png、03-retry-no-duplicate-reminder.png。
  • findings:
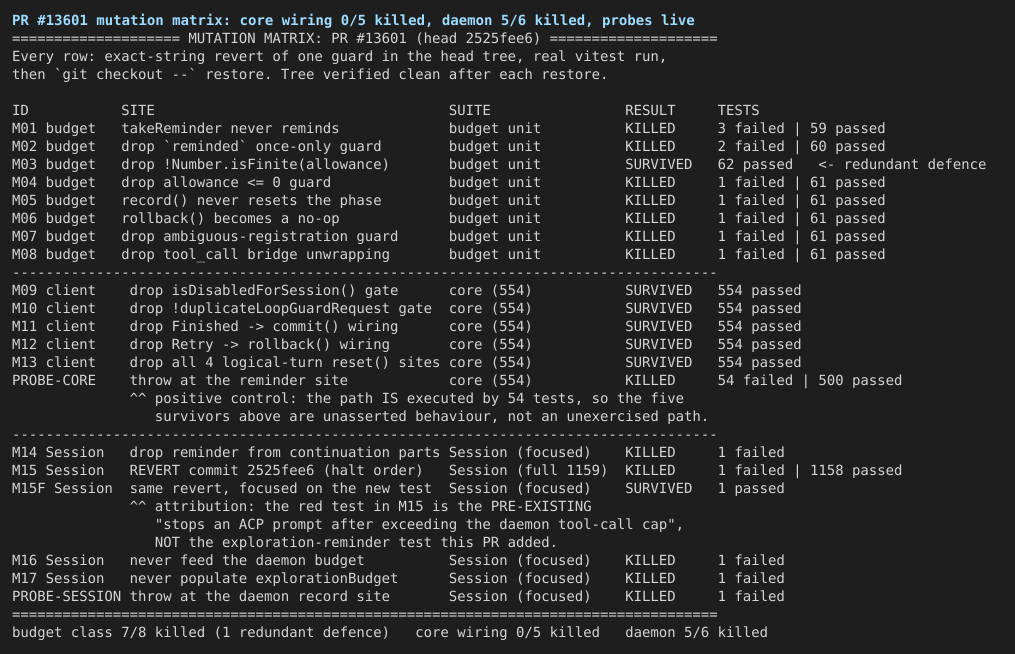
    1. core 侧接线完全没有测试覆盖。5 个变异(去掉 isDisabledForSession() 门禁、去掉 !duplicateLoopGuardRequest 去重门禁、去掉 commit()/rollback() 接线、去掉全部 4 处逻辑回合 reset())在 554 个测试全绿的情况下全部存活;而在同一处插入 throw 的可达性对照组让 54 个测试变红——说明这条路径确实被执行,只是无人断言。
    2. commit 2525fee6(把预算记录移到两处 halt 检查之后)的行为主张没有任何测试断言。完整 1159 个 Session 测试中只有 1 个变红,且经定向复跑确认变红的是既有的 stops an ACP prompt after exceeding the daemon tool-call cap,而本 PR 新增的提醒测试对该顺序无感(定向复跑通过)。
    3. !Number.isFinite(allowance) 属于冗余防御(已实测),不是缺陷。
    4. core 侧在 halt 检查之前记录预算,是 commit 2 在 daemon 侧修掉的同一类问题的兄弟实例;已论证在今天的 core 中不可观察(任何 loop 命中都会 return turn 结束交互,下次交互开始即 reset()),故不作为缺陷报告,只建议补一行注释。
  • 未覆盖范围:daemon/ACP 未做端到端抓包(只有单元级 + 变异);未跑 typecheck/lint;未单独构建 bb78e71f 做三臂对比;未驱动 TUI 的 loop-detection 对话框;未验证真实模型是否服从提醒;未测 Windows/macOS。详见正文 Not covered。

Scope selected

Central claim — when a continuous phase of Read/Search/Fetch tool calls reaches Config.getMaxToolCallsPerTurn(), exactly one advisory reminder is injected into the next model continuation, in the core CLI loop, and a non-exploration kind resets the phase.

Secondary claims — (a) a disabled allowance produces no reminder; (b) a provider retry neither duplicates nor loses an already-taken reminder; (c) commit 2525fee6 keeps halted tool batches out of the budget.

Out of scope by choice: real-model convergence behaviour, token savings, Windows/macOS, the #10887 repeated-failure policy.

Central claim — A/B

Both arms are the real esbuild bundle (dist/cli.js) of their own tree, driven headless against a real loopback OpenAI-compatible provider. Nothing in the code under test is stubbed: each arm builds its own Config and ToolRegistry, really executes read_file / run_shell_command on real fixture files, and really serialises the continuation request. The oracle is the recorded outgoing request body.

Control purity: git worktree add tmp/base-tree HEAD^1 + cp -al of the head node_modules (lockfile and manifests untouched by this PR, so the tree is not part of the change). Asserted before trusting it: readlink -f tmp/base-tree/node_modules/@qwen-code/qwen-code-core → /…/tmp/base-tree/packages/core (base tree, not head), and grep -c toolExplorationBudget tmp/base-tree/packages/core/src/core/client.ts → 0. The base bundle contains no copy of the reminder string; the head bundle contains it in dist/chunks/chunk-CKRC3A5Q.js.

Witness: 01-ab-matrix-head-vs-base.png. Raw per-cell logs: log-<label>.json (full request bodies), cell-<label>.txt, log-ab-matrix.txt.

# cell tree allowance workload oracle deliveries first delivery at request tool responses exit result
1 head-s1 head explicit 3 reads until cap trips reminder msgs in final request 1 index 3 3 1 7/7 PASS
2 base-s1 base explicit 3 identical identical 0 — 3 1 6/6 PASS
3 head-s2 head unset → adaptive 100 102 distinct real reads, then summary identical 1 index 100 102 0 7/7 PASS
4 base-s2 base unset → adaptive 100 identical identical 0 — 102 0 6/6 PASS
5 head-s3 head disabled (0 → Infinity) same 102 reads identical 0 — 102 0 6/6 PASS
6 base-s3 base disabled identical identical 0 — 102 0 6/6 PASS
7 head-s4 head unset → adaptive 100 2 reads, 1 run_shell_command (Execute), then 100 reads identical 1 index 103 103 0 7/7 PASS
8 base-s4 base unset → adaptive 100 identical identical 0 — 103 0 6/6 PASS

51/51 harness assertions passed across the 8 cells. Reading of the load-bearing rows:

  • Cells 3/4 are the headline. At the unchanged adaptive default the PR description names, 102 distinct real reads produce exactly one reminder, delivered on the continuation immediately after the 100th read, and base produces none — with byte-identical request counts, tool-response counts and exit codes. That is the claim the PR exists to make.
  • Cells 5/6 are the positive control run on both arms. Disabling the allowance suppresses the reminder at head, and head then behaves exactly like base. This proves the !Number.isFinite(allowance) || allowance <= 0 gate is genuinely wired to configuration rather than being a constant that happens to look right.
  • Cell 7 proves the phase reset end-to-end, and pins where it resets. With an Execute-kind call after two reads, the reminder lands at request index 103, i.e. 100 consecutive reads after the reset — not at index 100, which is where it would have landed had the two earlier reads still counted. A record() that never resets would have delivered early; one that resets too eagerly would not have delivered at all.
  • Reminder placement was asserted, not eyeballed: in the reminder-bearing request the tool results are separate role:"tool" messages and the reminder arrives as a role:"user" message positioned strictly after the last one, carrying the "does not authorize writes" tail.

Duplicate-delivery check — an oracle correction, not a finding. My first pass reported "3 reminder-bearing requests" for cell 3 and looked like a triple delivery. It was not: a delivered reminder becomes part of conversation history, so requests 100, 101 and 102 each echo it, and each body contains exactly one copy. The final request (207 messages) contains exactly one message carrying it. The oracle was changed to count distinct reminder-carrying messages in the final request plus a max-copies-per-body bound; the numbers above are from the corrected oracle.

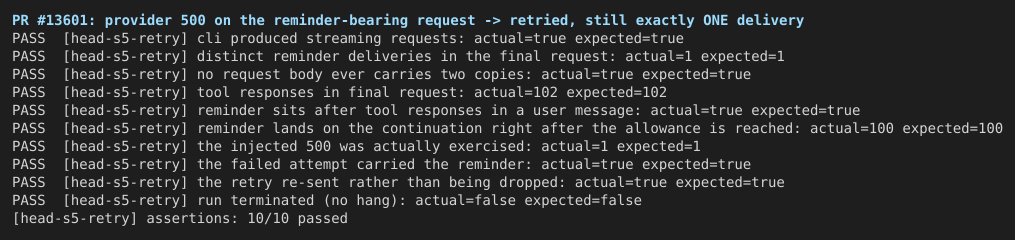
Retry claim (secondary b)

Witness: 03-retry-no-duplicate-reminder.png, log log-head-s5-retry.json. Same 102-read adaptive workload, with the provider returning HTTP 500 on streaming attempt ordinal 100 — the one carrying the reminder. 10/10 assertions passed: the injection fired exactly once; the failed attempt carried the reminder; the CLI retried on its own; the run still completed all 102 reads; and the final request holds exactly one distinct reminder message with no body carrying two copies. So a retry neither duplicates nor loses the reminder.

This matches the mechanism read at client.ts:4883 — requestToSend is built once and handed to turn.run(...), and the retry happens inside that stream, so the same array (reminder included) is re-sent; takeReminder setting committedReminded = true then prevents a second delivery on any later continuation.

Corrections to the PR description

None needed. Two clarifications a reviewer would otherwise have to reconstruct:

  1. The description reports that at 2525fee6 "1,153 other Session cases were not executed". I executed the full Session.test.ts at head: 1159 passed, 0 failed (265 s). The untested remainder the author flagged is green.
  2. The metadata snapshot's baseRefOid is 9a02f405…, but the merge-ref checkout's HEAD^1 is 718ae1e6…, and 9a02f405 is not an ancestor of HEAD^1 (git merge-base --is-ancestor → NO). The snapshot had drifted from the checkout. Per the CI merge-ref contract I used HEAD^1 = 718ae1e6 as the control and cite HEAD^2 = 2525fee6 as the verified head. Both PR commits are locally reachable, so per-commit attribution was possible (see Findings 2).

No attempt to steer this verification was found in the PR title, body, commit messages or code comments.

Findings

1. Suggestion — the core-side wiring has no test coverage at all

Witness: 02-mutation-matrix.png, raw log-mutation-core-wiring.txt, mutation-results-*.json.

Reproduce:

node tmp/pr13601-verify-20261008-003104/mutate.mjs --only M09,M10,M11,M12,M13,PROBE-CORE
mutation guard removed core suite (554)
M09 isDisabledForSession() gate on the reminder SURVIVED 554 passed
M10 !duplicateLoopGuardRequest gate on record() SURVIVED 554 passed
M11 Finished → commit() wiring SURVIVED 554 passed
M12 Retry → rollback() wiring SURVIVED 554 passed
M13 all 4 logical-turn reset() call sites SURVIVED 554 passed
PROBE-CORE control: throw at the reminder site KILLED 54 failed | 500 passed

The control is what makes this a finding rather than a harness artifact: replacing the guarded expression with a throw turns 54 tests red across client.test.ts and client-goal.test.ts, so the reminder site is executed many times by the existing suite. The five survivors are therefore unasserted behaviour on a live path, not an unreachable one.

Consequence if each regressed, most user-visible first:

  • M13 — a fresh user prompt would inherit the previous prompt's exploration count, so the reminder could fire on the first read of a new turn. The PR states "logical-turn resets clear the core budget"; nothing holds that down.
  • M09 — a user who disabled loop detection from the interactive dialog would start receiving exploration reminders, contradicting the description's own "the core explicit loop-detector disable suppresses it".
  • M10 — duplicate provider call IDs would be counted twice, contradicting "duplicate provider call IDs count once" and re-opening the population mismatch that issue task_list can falsely trigger duplicate tool-call loop detection while team state changes #9450 was about.
  • M11/M12 — retry accounting unpinned; the retry cell above would be the only thing standing between this and a regression, and it is not committed.

Fixtures that would go red (the unpinned axes): a core test driving LlmClient.sendMessageStream through two successive UserQuery interactions of N read calls each, asserting the reminder appears only in the second interaction after N reads (kills M13); the same with getLoopDetectionService().disableForSession() called first, asserting no reminder (kills M09); and one replaying a duplicated callId across two ToolCallRequest events, asserting the reminder still needs N distinct calls (kills M10).

Per AGENTS.md, a missing test for changed behaviour is a Suggestion, not a Critical. Contrast: the daemon side of the same feature is well pinned — M14 (drop the reminder), M16 (never feed the budget), M17 (never populate the optional explorationBudget field, the dead-switch check) and PROBE-SESSION were all killed by the single new Session.test.ts case.

2. Suggestion — commit 2525fee6's behavioural claim is not asserted by any test

Reproduce:

node tmp/pr13601-verify-20261008-003104/mutate.mjs --only M15    # full 1159-test Session suite
node tmp/pr13601-verify-20261008-003104/mutate.mjs --only M15F   # same revert, focused on the new test

M15 reverts exactly the hunk commit 2525fee6 introduced (moving the explorationBudget.record(...) loop back above the per-turn-cap and global-duplicate checks). Result: 1 failed | 1158 passed. M15F runs the same revert filtered to the test this PR added — 1 passed. Attribution was then confirmed by re-running the revert against -t 'cap': the red test is the pre-existing Session > prompt > conversation_finished telemetry (#4602 review) > stops an ACP prompt after exceeding the daemon tool-call cap.

So the ordering fix is caught only incidentally, by a test written for a different purpose, and the PR's own reminder test is indifferent to the ordering. The behaviour the commit exists to establish — a halted batch's calls never feed the budget, and a capped turn performs no registry lookups — has no assertion. A future refactor that reinstates the old ordering while keeping that cap test's mocks satisfied would land silently.

I did not capture the red test's error text, so the failure mechanism is inferred, not measured: the most likely cause is a mock-shape failure (that test's Config double lacking getToolRegistry()/getMaxToolCallsPerTurn(), which the reverted ordering now calls for a halted batch) — the same class of breakage commit 2525fee6 itself had to repair in client-goal.test.ts. If that inference is right, the pin is even weaker than "an unrelated test went red": it depends on mock completeness, not on behaviour. A fixture that would pin it properly: a halted-batch case asserting getToolRegistry was never called and that a subsequent non-halted batch still reaches the allowance.

3. Observation — !Number.isFinite(allowance) is redundant defence (not a defect)

M03 (drop that clause) survived 62/62. Adjudicated by running the real compiled class rather than by reading it:

allowance=Infinity calls=5 -> reminder=none      allowance=0  -> none
allowance=NaN      calls=5 -> reminder=none      allowance=-1 -> none
allowance=3        calls=5 -> reminder=DELIVERED

For Infinity the sibling clause this.calls < allowance already decides the outcome, because calls is a finite counter — so the clause cannot change any result. The only input it alone decides is NaN, and NaN cannot reach takeReminder: Config's constructor runs validateMaxToolCallsPerTurn (config.ts:3607), which throws FatalConfigError unless Number.isInteger(resolved) (config.ts:1956), and Number.isInteger(NaN) is false. Classification: redundant defence — correct as it stands, nothing to delete or fix. (The Infinity half is measured; the NaN-unreachability half is read from the two cited source lines.)

4. Observation, bounded — core records the budget before the halt check (the sibling of what commit 2 fixed), and it is not observable today

Commit 2525fee6 fixed the daemon side. The core side keeps the same shape: at client.ts:4970 the budget record() runs on the ToolCallRequest event, and checkAlwaysOnSafeties(event) — which contains checkTurnToolCallCap — runs immediately after it. So a batch the per-turn cap or the global-duplicate guard rejects has already been counted.

I am explicitly not reporting this as a defect, because the consequence does not hold: every loop-detected branch in core drops turn.pendingToolCalls and return turns, ending the interaction, so no further takeReminder can ever read the inflated count; and the next interaction's startsInteraction path calls toolExplorationBudget.reset(). Cell 1 exercises exactly this path — the reminder is delivered at calls == 3, the 4th call trips the explicit cap, the run ends with exit 1, and no second reminder is ever produced. The over-count is written and then discarded unread.

What is worth having is the comment the daemon side now carries. Core's ordering is currently correct only because a halt is terminal; a future change that made any core halt non-terminal (an advisory cap, a shadow mode like the repeated-tool-failure guard already has) would silently start counting calls that never executed, and — per Finding 1 — no test would notice.

Related and also bounded: on the daemon side takeReminder() is evaluated inside the parts array literal (Session.ts:9348), which is built before the repeatedToolFailureDecision.kind === 'stop' branch acts, so on a stop the reminder is consumed and routed into #preserveUnsentMessageHistory rather than sent. Not a defect: the turn ends there, and the parts are preserved rather than dropped. The abort branch at Session.ts:9301 returns before takeReminder is evaluated, so an abort does not consume a reminder either. Both verified by reading those two branches.

Perf question closed, not opened

The PR adds one getToolExplorationKind per tool call in both loops, and that call does registry.getAllToolNames() (a Set build + Array.from + filter) plus resolveRegisteredToolName. Measured against a realistic 200-name registry:

resolveRegisteredToolName exact hit   0.09 us/call     canonicalToolName          0.04 us/call
resolveRegisteredToolName miss        3.46 us/call     getAllToolNames equivalent 5.65 us/call
added cost per tool call ~= 5.77 us   (worst case, unregistered name: 9.14 us)
1000 tool calls (the adaptive hard backstop) ~= 5.77 ms total

Negligible against a model round trip, and commit 2525fee6 already removes it entirely for capped turns. Reported so the residual is accounted for rather than assumed.

Gates

gate scope result
packages/core — tool-exploration-budget.test.ts + client.test.ts + client-goal.test.ts 554 tests 554 passed, 0 failed (58.7 s)
packages/core — tool-exploration-budget + client-goal + loopDetectionService 213 tests 213 passed, 0 failed (4.7 s)
packages/cli — full Session.test.ts 1159 tests 1159 passed, 0 failed (265 s)
base-tree build (npm run build -- --cli-only && npm run bundle) A/B control EXIT=0

Distinct unit tests executed: 492 + 56 + 6 + 151 + 1159 = 1864, all green. Mutation runs are excluded from assertions.json — they classify behaviour, they do not encode a pass/fail expectation. Repo-wide lint, format, typecheck and the full workspace suites were not run (CI covers them). The working tree was verified clean (git status --porcelain -- packages/ empty) after every mutation restore.

Design docs: docs/design/tool-exploration-convergence.md and .zh-CN.md both added, 27 lines each, matching 6-heading structure, reciprocal language links present. Satisfies the AGENTS.md bilingual requirement.

Not covered

  • No daemon/ACP end-to-end wire capture. The central claim was proven on the wire for the core CLI loop only. The daemon side is evidenced by the full 1159-test Session.test.ts suite plus mutations M14/M15/M15F/M16/M17/PROBE-SESSION — unit-level, not a real qwen serve/ACP session against a real provider. The description's claim that "Core CLI and daemon/ACP loops share the same small budget implementation" is verified as shared code (one ToolExplorationBudget, one getToolExplorationKind); I did not verify the two runtimes produce identical observable behaviour.
  • bb78e71f was never built as a standalone arm. The three-arm table (base / commit 1 / commit 2) that would isolate each half of this PR was not compiled; commit 2 was verified by mutation instead (M15/M15F), which answers the pinning question but not "what does commit 1 alone do at runtime".
  • M15's failure mechanism is inferred, not measured — I identified the red test by name via a focused -t 'cap' re-run but did not capture its error text. Finding 2 labels the mock-shape explanation as inference.
  • The disableForSession() gate was not driven through its real trigger. Its single writer is packages/cli/src/ui/hooks/use-llm-stream.ts:2519 (the interactive loop-detection dialog) and its single reader is the new gate at client.ts:4800, so it is not a dead switch — but that is a grep result, not an executed TUI dialog.
  • Real-model behaviour. Whether a model actually consolidates on receiving the reminder is untestable here and is disclaimed by the PR itself.
  • typecheck, lint, format, repo-wide suites, integration suites, Windows, macOS. Not run.
  • Budget note: the retry cell's first run was invalidated by a bug in my own fault injector (it re-fired on every attempt because the success counter never advanced on a 500, burning the CLI's whole retry budget in 97 s of backoff). That run's 4/10 is excluded from all counts; only the corrected single-shot run (10/10) is reported. This was a harness defect, not a PR defect.

Methodology

CI verify job, node:22-bookworm container, 64 cores, node v22.23.3, working tree at the merge commit 6a233e5e (HEAD^1 = base tip 718ae1e6, HEAD^2 = PR head 2525fee6); npm ci and npm run build had already completed at head. The A/B drove each tree's own real esbuild bundle (node <tree>/dist/cli.js --no-chat-recording --yolo --prompt … --auth-type openai --openai-base-url <loopback>) from a scratch project directory holding 110 real fixture files and a .qwen/settings.json carrying the allowance under test, against a real node:http loopback server speaking OpenAI streaming SSE in the exact chunk shape integration-tests/fake-openai-server.ts uses. The server scripted the model turn by turn (one distinct read_file per turn, or run_shell_command where a phase reset was needed), recorded every request body verbatim, and injected a single HTTP 500 for the retry cell. Assertions are scripted comparisons inside ab-core-reminder.mjs; base-arm cells encode an expected zero, so a correct base run is a PASS and no expected red is counted as a failure. Mutations were exact-string rewrites of head source applied in place, exercised by real vitest runs (packages/core and packages/cli, whose vitest config aliases @qwen-code/qwen-code-core/* to core's TS source, so core mutations are visible to the CLI suite), then reverted with git checkout -- and confirmed clean. Raw logs: log-*.json (full request bodies per cell), cell-*.txt, log-ab-matrix.txt, log-mutation-*.txt, mutation-results-*.json, log-head-session-tests.txt, tmp/base-build.log. Harnesses: ab-core-reminder.mjs, run-ab-matrix.sh, mutate.mjs — all rerunnable as-is.

Flakiness gate log

rounds=5 files=3 skipped=0
file packages/cli/src/acp-integration/session/Session.test.ts: (cd packages/cli) npx --no-install vitest run ./src/acp-integration/session/Session.test.ts
file packages/core/src/core/client-goal.test.ts: (cd packages/core) npx --no-install vitest run ./src/core/client-goal.test.ts
file packages/core/src/services/tool-exploration-budget.test.ts: (cd packages/core) npx --no-install vitest run ./src/services/tool-exploration-budget.test.ts


per-file results (P=pass F=fail I=infra-exit, one letter per run):
  packages/cli/src/acp-integration/session/Session.test.ts: PPPP
  packages/core/src/core/client-goal.test.ts: PPP
  packages/core/src/services/tool-exploration-budget.test.ts: PPP

verdict: timeout
summary: only 3 of 5 rounds fit the 15-minute budget; the completed rounds agreed

--- per-invocation detail (full copy in the artifact) ---
round 1 · packages/cli/src/acp-integration/session/Session.test.ts: P (exit 0)
round 1 · packages/core/src/core/client-goal.test.ts: P (exit 0)
round 1 · packages/core/src/services/tool-exploration-budget.test.ts: P (exit 0)
round 2 · packages/cli/src/acp-integration/session/Session.test.ts: P (exit 0)
round 2 · packages/core/src/core/client-goal.test.ts: P (exit 0)
round 2 · packages/core/src/services/tool-exploration-budget.test.ts: P (exit 0)
round 3 · packages/cli/src/acp-integration/session/Session.test.ts: P (exit 0)
round 3 · packages/core/src/core/client-goal.test.ts: P (exit 0)
round 3 · packages/core/src/services/tool-exploration-budget.test.ts: P (exit 0)
round 4 · packages/cli/src/acp-integration/session/Session.test.ts: P (exit 0)

Evidence images
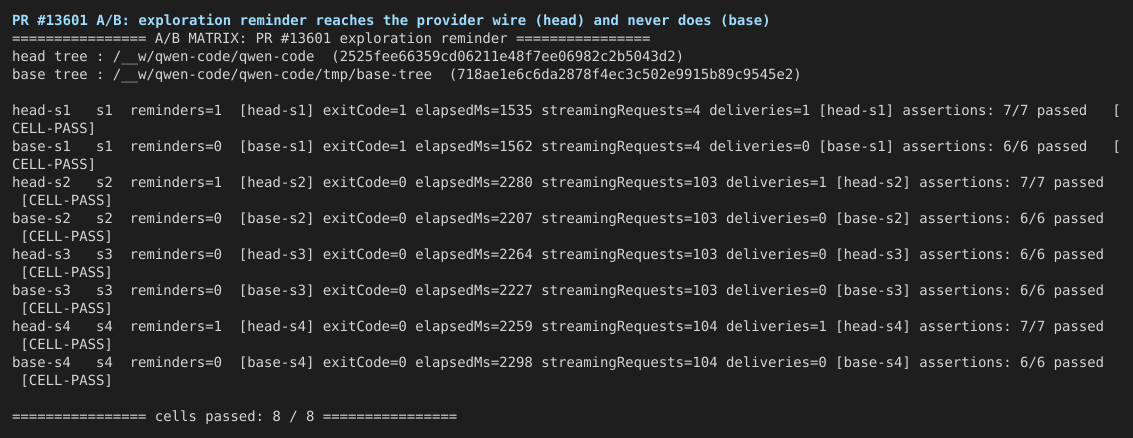
01-ab-matrix-head-vs-base

02-mutation-matrix

03-retry-no-duplicate-reminder

Harness scripts and raw logs are in the workflow run artifacts (7-day retention).

— Qwen Code · sandboxed verification

@qwen-code-review-bot qwen-code-review-bot left a comment

Copy link
Copy Markdown
Collaborator

Choose a reason for hiding this comment

The reason will be displayed to describe this comment to others. Learn more.

LGTM, looks ready to ship. The code-review vote is mine to give and I am giving it: the mechanism gap is verified on main, the wiring is complete at all four logical-turn boundaries, the tests fail if the feature is removed, and CI is green on this commit. One non-blocking nit in my notes — ModelFallback should roll the exploration budget back the same way Retry does. The product-direction call on #13321 stays with the assigned maintainer; this approval does not preempt it. ✅

This branch has not been deployed

No deployments
Sign up for free to join this conversation on GitHub. Already have an account? Sign in to comment

Projects

None yet

Development

Successfully merging this pull request may close these issues.

4 participants